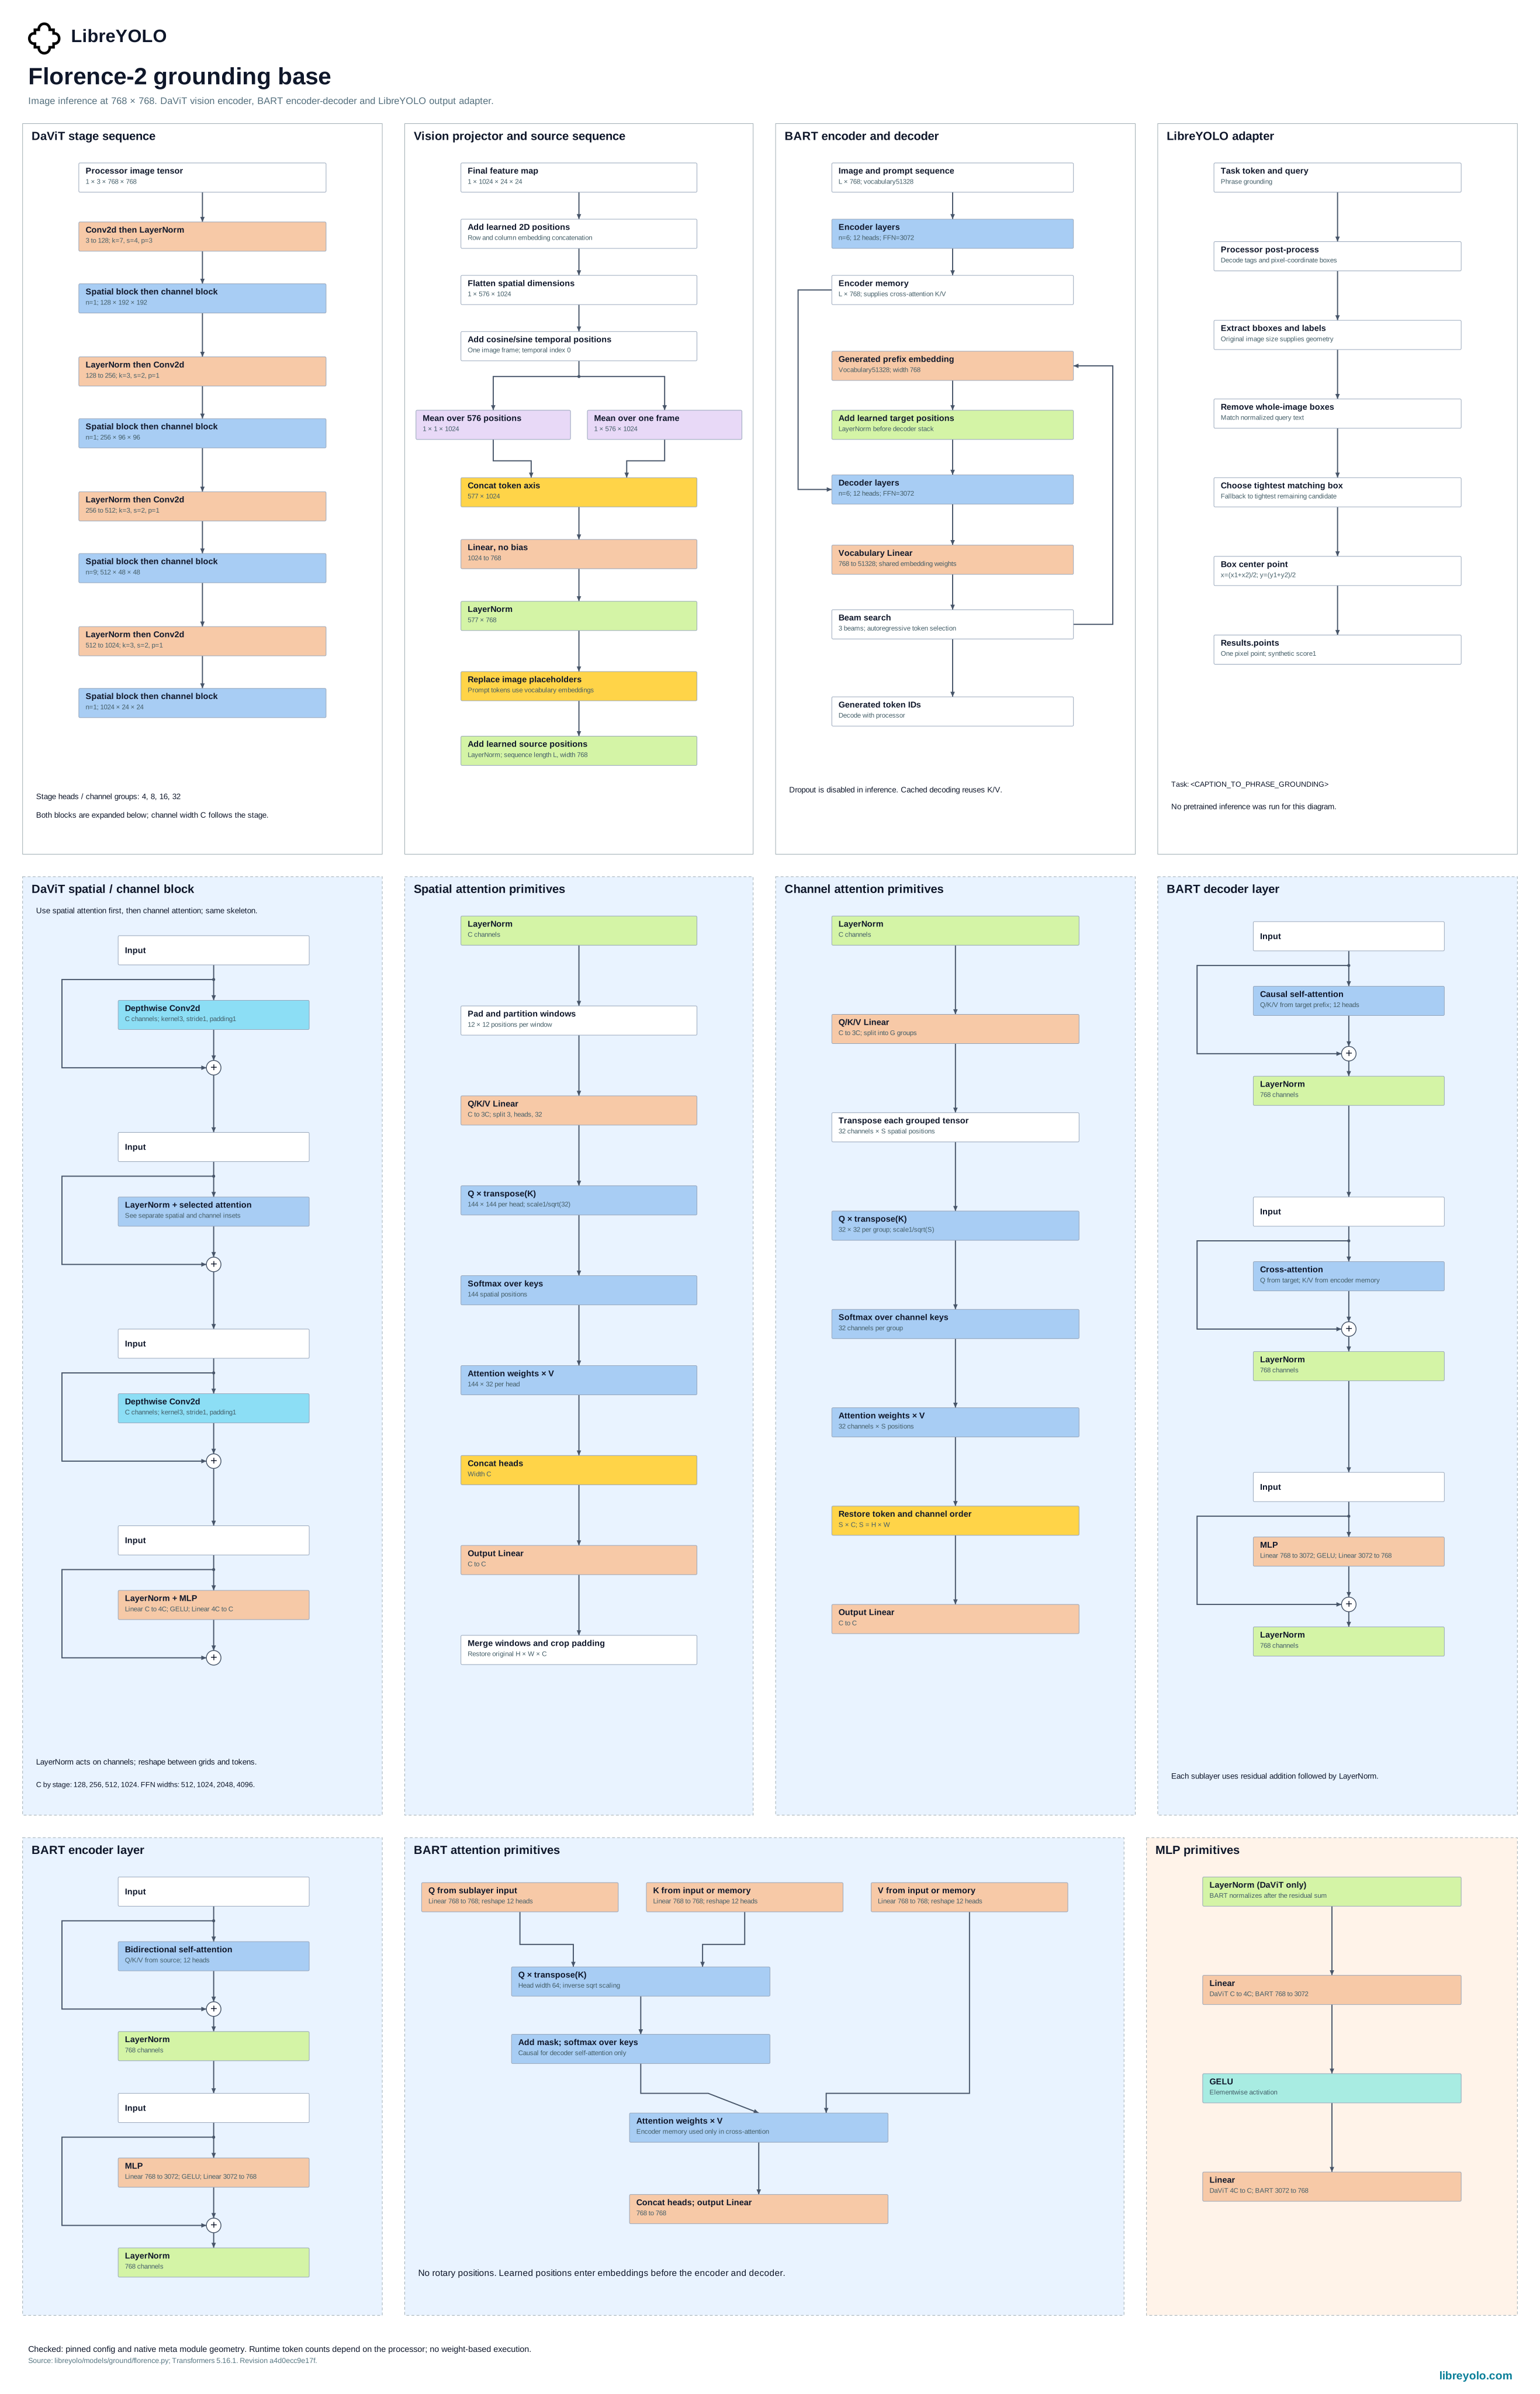
Florence-2 grounding
Florence-2 grounding locates the target of an instruction as an image point.
- Tasks
- point detection
- Sizes
- base, large at 768 px
- Install
pip install "libreyolo[vlm]"- Support tier
- Sibling tier, since v1.6.0. A separate product surface with its own factory and contract.
- Licenses
- Code MIT, weights MIT. Commercial use
Install
pip install "libreyolo[ground]"Predict
from libreyolo import LibreGround, SAMPLE_IMAGE model = LibreGround("florence-2-base", device="cpu")result = model(SAMPLE_IMAGE, prompt="the person")print(result.points.xy)Use prompt= or query= for one call, or set_query() for a persistent instruction. A list of instructions on one image returns at most one click per query. Multi-query calls on image lists or folders raise an error. Coordinates refer to the original image. Training, validation and export are not supported. See the grounding API.
Licensing
Check the license on the Hugging Face repository of the specific weights you download. Every checkpoint in the LibreYOLO org carries one, and they are not always the same across a family. That repository is the authoritative source; the summary below describes what applied when this page was last verified.
This is a description of the licenses involved, not legal advice. If the answer matters commercially, read the licenses yourself and take your own counsel.
- Original work
- Florence-2, Microsoft
- Upstream license
- MIT
- Upstream source
- huggingface.co/microsoft/Florence-2-base
- LibreYOLO code
- MIT
- Weights
- MIT, republished at huggingface.co/LibreYOLO
- Interpretation
- The model publisher declares MIT.
Citation
@article{xiao2023florence,
  title={Florence-2: Advancing a unified representation for a variety of vision tasks},
  author={Xiao, Bin and Wu, Haiping and Xu, Weijian and Dai, Xiyang and Hu, Houdong and Lu, Yumao and Zeng, Michael and Liu, Ce and Yuan, Lu},
  journal={arXiv preprint arXiv:2311.06242},
  year={2023}
}
Copied from the authors' citation block at huggingface.co/microsoft/Florence-2-large#bibtex.