V-JEPA 2
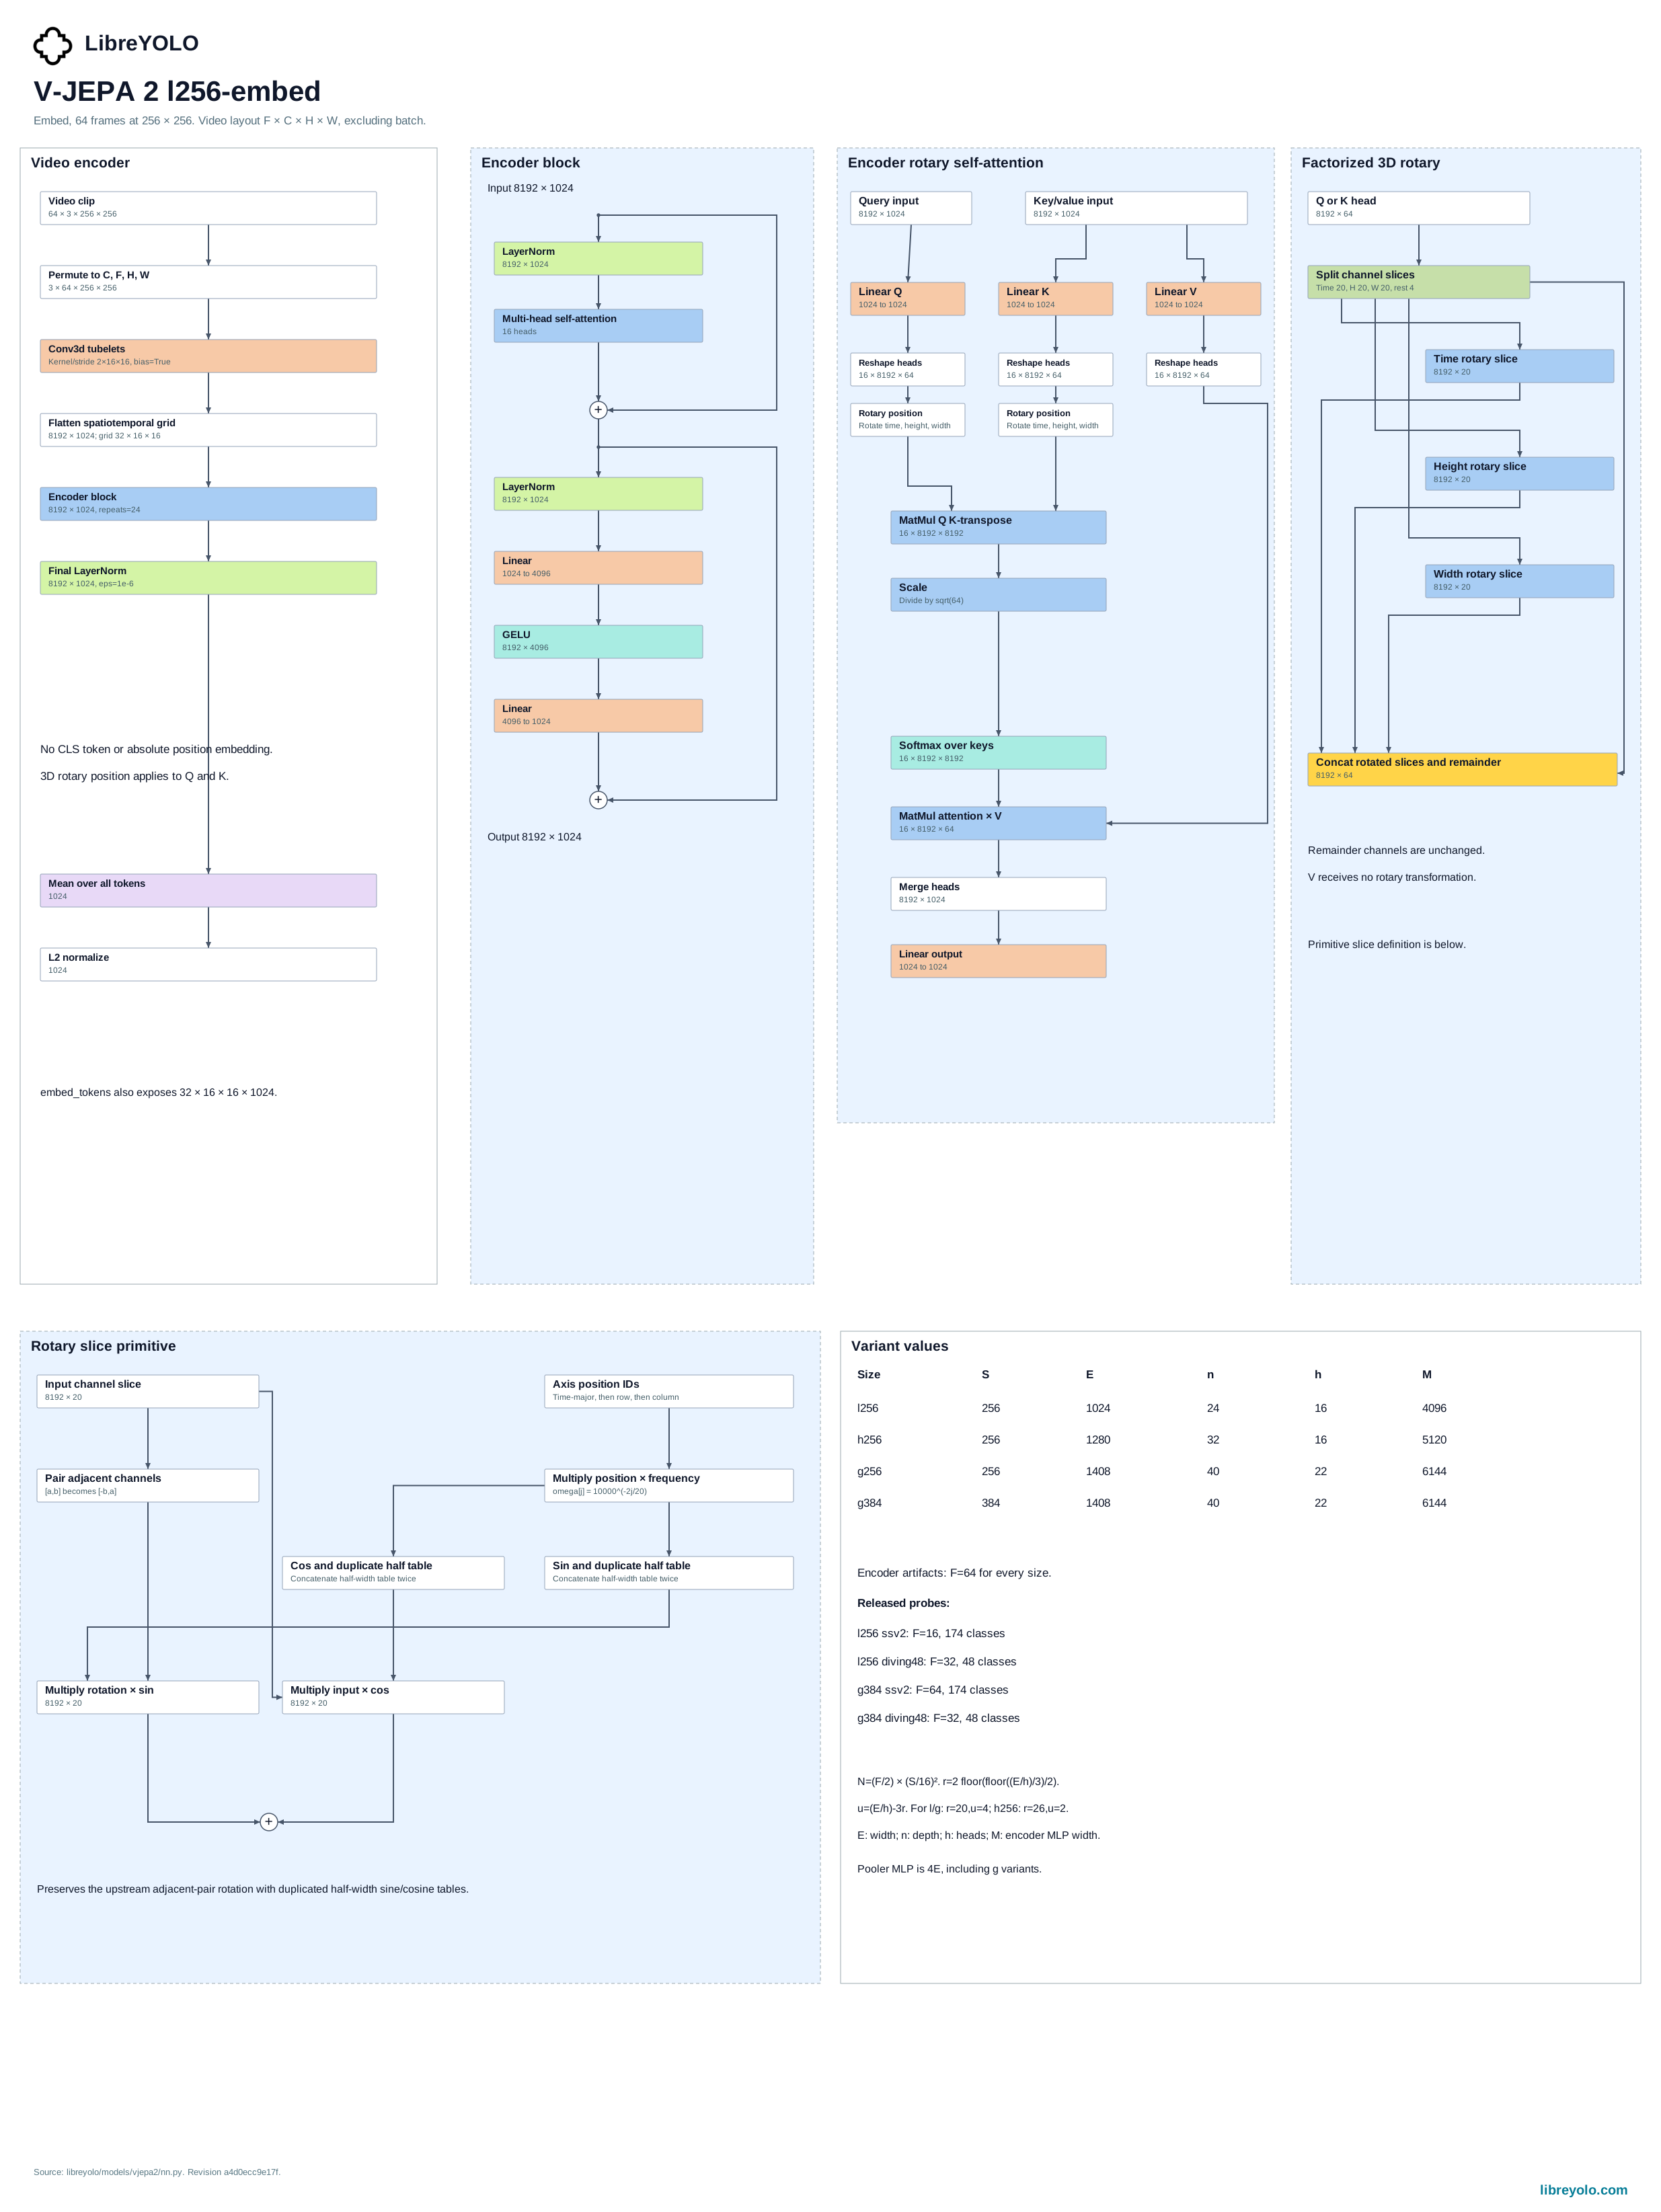
V-JEPA 2 produces video embeddings and supports training an attentive classification probe.
- Tasks
- embeddings, classification
- Sizes
- l256, h256, g256, g384 at 256 to 384 px
- Install
pip install libreyolo- Support tier
- Supported, since v1.6.0. Supporting trainables: kept green in CI, features land opportunistically.
- Licenses
- Code MIT, weights MIT; Apache-2.0 for giant encoder artifacts. Commercial use
Install
pip install "libreyolo"Predict
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibreVJEPA2l256-embed.pt", device="cpu")result = model(SAMPLE_IMAGE)print(result.embeddings)tokens = model.embed_tokens(SAMPLE_IMAGE)print(tokens.shape)A still image is promoted to a clip. embed_tokens() returns (B, T, H, W, D) tokens; the public embedding normalizes their mean. Exported clip graphs require direct five-dimensional runtime input.
Train
Only the attentive probe and linear classifier train; the encoder stays frozen. Use the classification task and a video-manifest dataset. Defaults are 10 epochs, batch 2, learning rate 0.001 and workers 0. Full encoder fine-tuning and pretraining are not supported.
Dataset setup describes the required training data.
from libreyolo import LibreYOLO model = LibreYOLO("LibreVJEPA2l256-cls-ssv2.pt", device="cpu")# Replace with your video dataset YAML (train/val manifests of '<video-path> <class-id>' lines).model.train(data="path/to/your/video_dataset.yaml", epochs=1, device="cpu", workers=0)Validate
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibreVJEPA2l256-cls-ssv2.pt", device="cpu")# Replace with your video dataset YAML; val() reads its val manifest of '<video-path> <class-id>' lines.metrics = model.val(data="path/to/your/video_dataset.yaml", workers=0)print(metrics)Use the dataset format for this task. Validation explains the dataset requirements and returned metrics.
Export
| Task | ONNX | TorchScript | ExecuTorch | TensorRT | OpenVINO | Paddle | MNN | RKNN | ncnn | TFLite | CoreML | Core AI |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Embeddings | Embeddings to ONNX: supported | Embeddings to TorchScript: supported | Embeddings to ExecuTorch: supported | Embeddings to TensorRT: supported | Embeddings to OpenVINO: supported | Embeddings to Paddle: not supported | Embeddings to MNN: not supported | Embeddings to RKNN: not supported | Embeddings to ncnn: not supported | Embeddings to TFLite: not supported | Embeddings to CoreML: not supported | Embeddings to Core AI: not supported |
| Classification | Classification to ONNX: supported | Classification to TorchScript: supported | Classification to ExecuTorch: supported | Classification to TensorRT: supported | Classification to OpenVINO: supported | Classification to Paddle: not supported | Classification to MNN: not supported | Classification to RKNN: not supported | Classification to ncnn: not supported | Classification to TFLite: not supported | Classification to CoreML: not supported | Classification to Core AI: not supported |
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibreVJEPA2l256-embed.pt", device="cpu")model.export(format="onnx")Export setup lists format dependencies and loading exported artifacts.
Checkpoints
| File | Weights license |
|---|---|
| Embeddings | |
| LibreVJEPA2h256-embed.pt | mit |
| LibreVJEPA2l256-embed.pt | mit |
| LibreVJEPA2g384-embed.pt | apache-2.0 |
| LibreVJEPA2g256-embed.pt | apache-2.0 |
| Classification | |
| LibreVJEPA2l256-cls-ssv2.pt | mit |
| LibreVJEPA2l256-cls-diving48.pt | mit |
| LibreVJEPA2g384-cls-diving48.pt | mit |
| LibreVJEPA2g384-cls-ssv2.pt | mit |
Every file above exists in the LibreYOLO org today and downloads on first use.
Licensing
Check the license on the Hugging Face repository of the specific weights you download. Every checkpoint in the LibreYOLO org carries one, and they are not always the same across a family. That repository is the authoritative source; the summary below describes what applied when this page was last verified.
This is a description of the licenses involved, not legal advice. If the answer matters commercially, read the licenses yourself and take your own counsel.
- Original work
- V-JEPA 2, Meta AI
- Upstream license
- MIT; Apache-2.0 for giant encoder artifacts
- Upstream source
- github.com/facebookresearch/vjepa2
- LibreYOLO code
- MIT
- Weights
- MIT; Apache-2.0 for giant encoder artifacts, republished at huggingface.co/LibreYOLO
- Interpretation
- Licenses differ by artifact: the two giant encoder artifacts are Apache-2.0; the other mirrored encoders and classification probes are MIT.