Perception Encoder
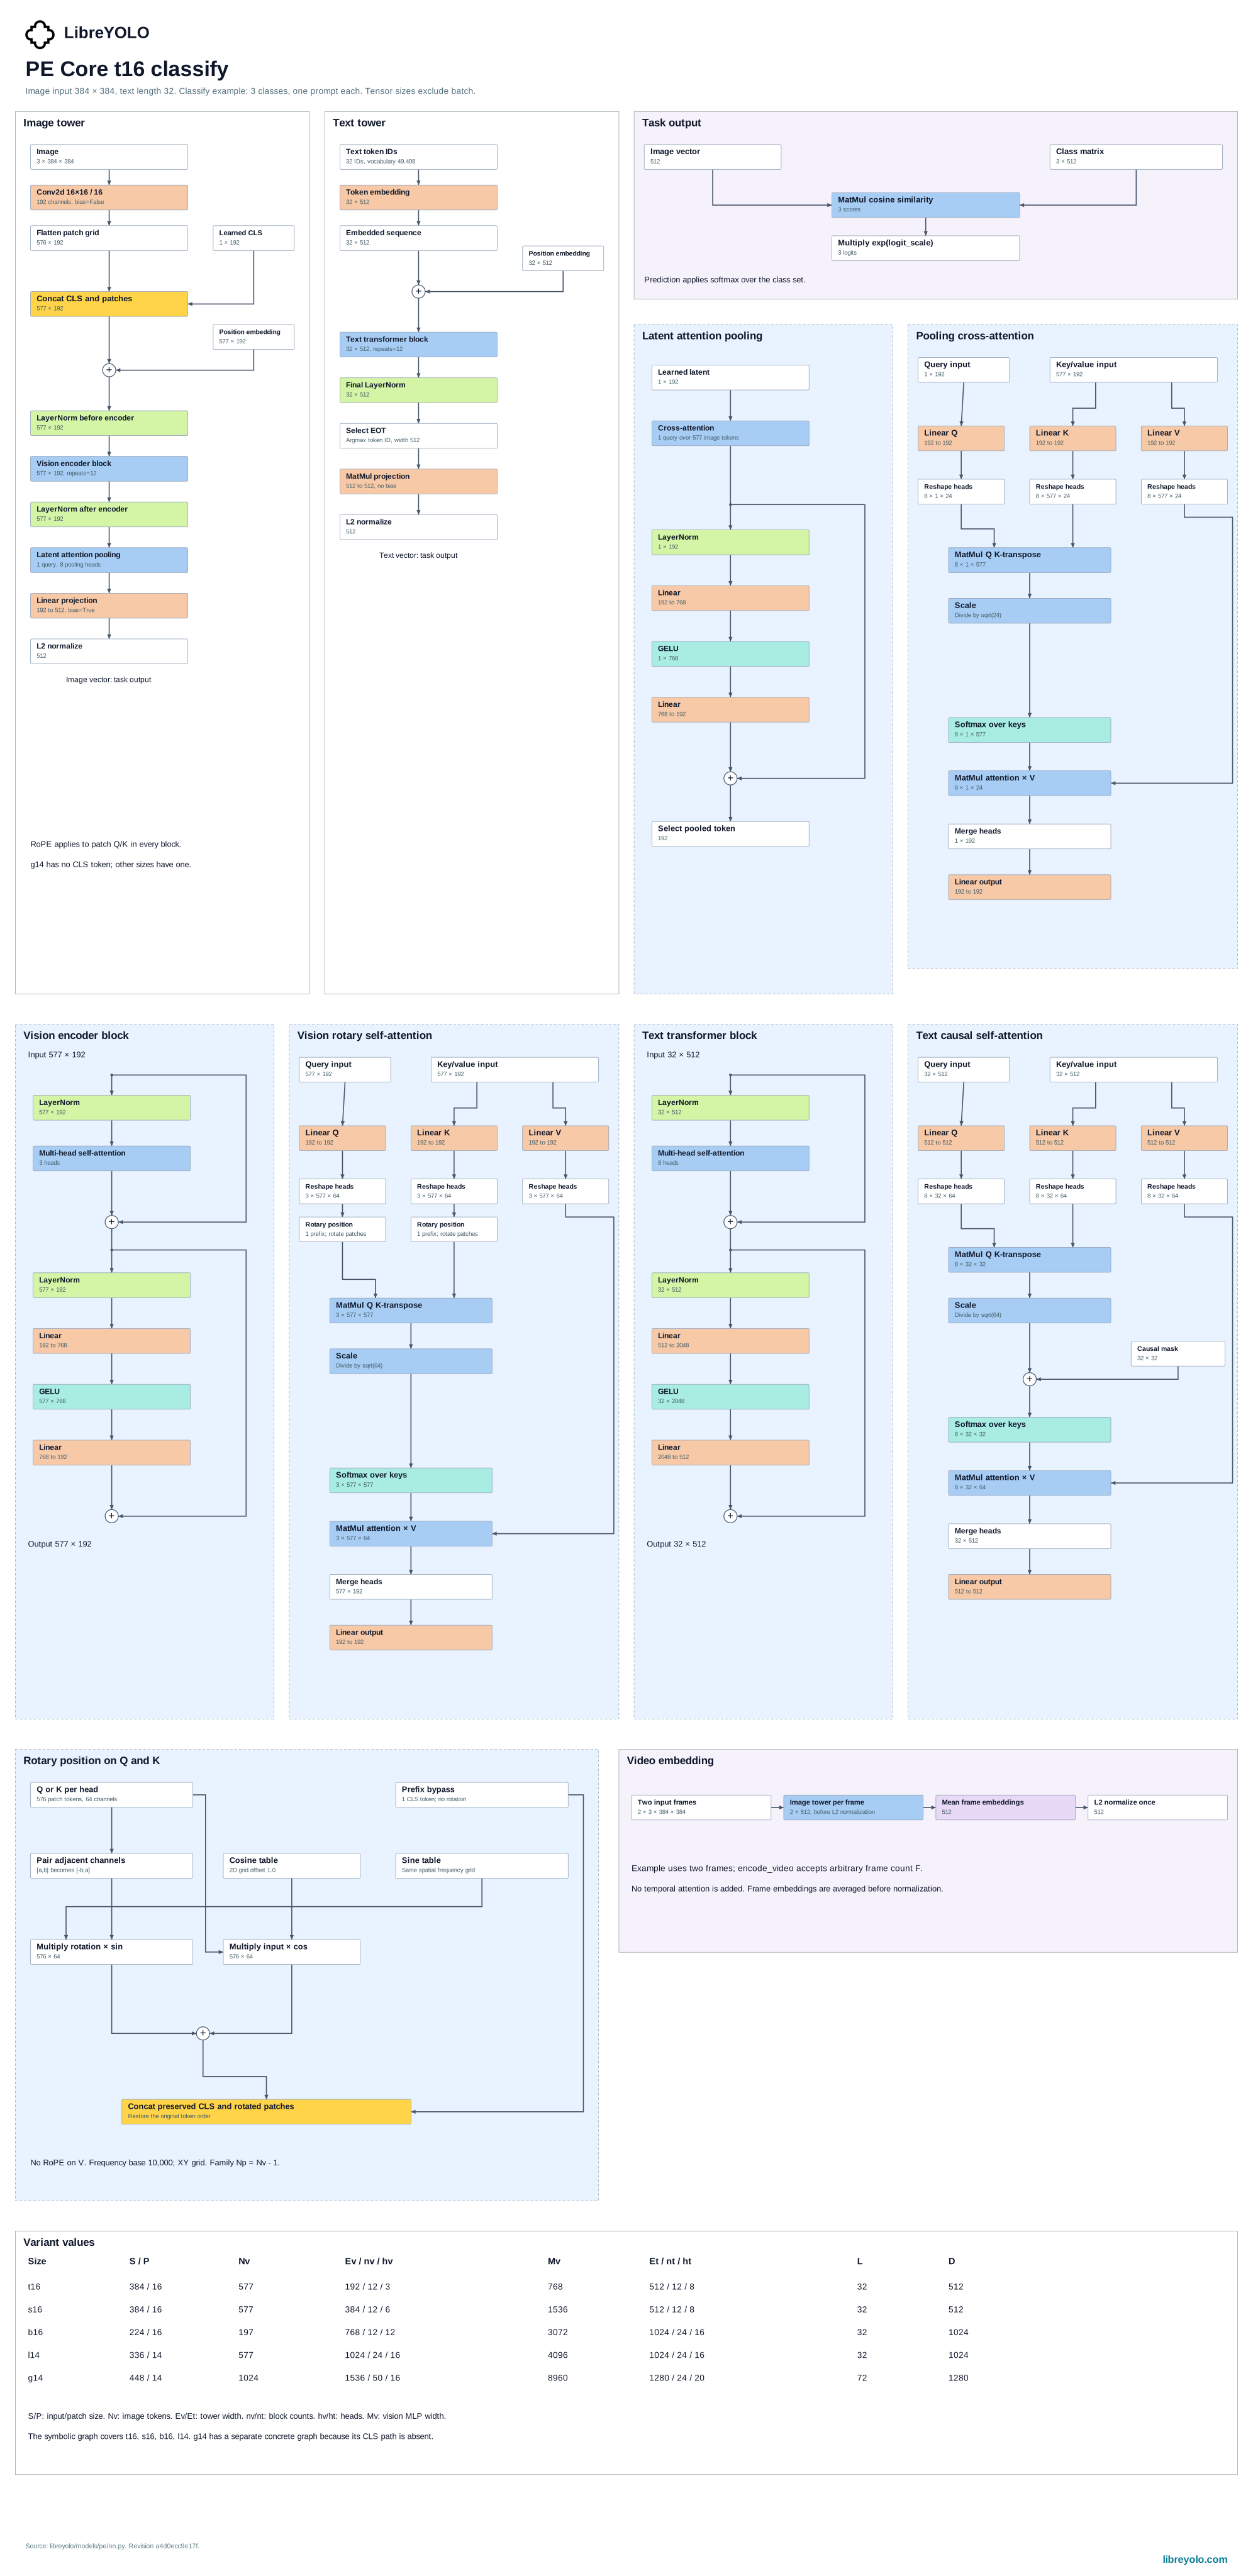
Perception Encoder maps images, text and finite video clips into a shared embedding space.
- Tasks
- classification, embeddings
- Install
pip install "libreyolo[clip]"- Support tier
- Sibling tier, since v1.6.0. A separate product surface with its own factory and contract.
- Licenses
- Code MIT, weights Apache-2.0. Commercial use
Install
pip install "libreyolo[clip]"Predict
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibrePEt16-cls.pt", device="cpu")model.set_classes(["person", "building"])result = model(SAMPLE_IMAGE)print(result.probs)Set classes before zero-shot classification. Select task="embed" when loading for embeddings. Video embedding samples clip_frames=8 frames by default, averages their vectors and L2-normalizes the result. Training is not supported. Exported video graphs take direct runtime input.
Export
| Task | ONNX | TorchScript | ExecuTorch | TensorRT | OpenVINO | Paddle | MNN | RKNN | ncnn | TFLite | CoreML | Core AI |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Classification | Classification to ONNX: supported | Classification to TorchScript: supported | Classification to ExecuTorch: supported | Classification to TensorRT: supported | Classification to OpenVINO: supported | Classification to Paddle: not supported | Classification to MNN: not supported | Classification to RKNN: not supported | Classification to ncnn: not supported | Classification to TFLite: not supported | Classification to CoreML: not supported | Classification to Core AI: not supported |
| Embeddings | Embeddings to ONNX: supported | Embeddings to TorchScript: supported | Embeddings to ExecuTorch: supported | Embeddings to TensorRT: supported | Embeddings to OpenVINO: supported | Embeddings to Paddle: not supported | Embeddings to MNN: not supported | Embeddings to RKNN: not supported | Embeddings to ncnn: not supported | Embeddings to TFLite: not supported | Embeddings to CoreML: not supported | Embeddings to Core AI: not supported |
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibrePEt16-cls.pt", device="cpu")model.export(format="onnx")Export setup lists format dependencies and loading exported artifacts.
Checkpoints
| File | Weights license |
|---|---|
| Classification | |
| LibrePEt16-cls.pt | apache-2.0 |
| LibrePEs16-cls.pt | apache-2.0 |
| LibrePEb16-cls.pt | apache-2.0 |
| LibrePEl14-cls.pt | apache-2.0 |
| LibrePEg14-cls.pt | apache-2.0 |
Every file above exists in the LibreYOLO org today and downloads on first use.
Licensing
Check the license on the Hugging Face repository of the specific weights you download. Every checkpoint in the LibreYOLO org carries one, and they are not always the same across a family. That repository is the authoritative source; the summary below describes what applied when this page was last verified.
This is a description of the licenses involved, not legal advice. If the answer matters commercially, read the licenses yourself and take your own counsel.
- Original work
- Perception Encoder, Meta AI
- Upstream license
- Apache-2.0
- Upstream source
- github.com/facebookresearch/perception_models
- LibreYOLO code
- MIT
- Weights
- Apache-2.0, republished at huggingface.co/LibreYOLO
- Interpretation
- The publisher declares Apache-2.0 for the encoder weights.
Citation
@article{bolya2025PerceptionEncoder,
  title={Perception Encoder: The best visual embeddings are not at the output of the network},
  author={Daniel Bolya and Po-Yao Huang and Peize Sun and Jang Hyun Cho and Andrea Madotto and Chen Wei and Tengyu Ma and Jiale Zhi and Jathushan Rajasegaran and Hanoona Rasheed and Junke Wang and Marco Monteiro and Hu Xu and Shiyu Dong and Nikhila Ravi and Daniel Li and Piotr Doll{\'a}r and Christoph Feichtenhofer},
  journal={arXiv:2504.13181},
  year={2025}
}
Copied from the authors' citation block at raw.githubusercontent.com/facebookresearch/perception_models/main/README.md.