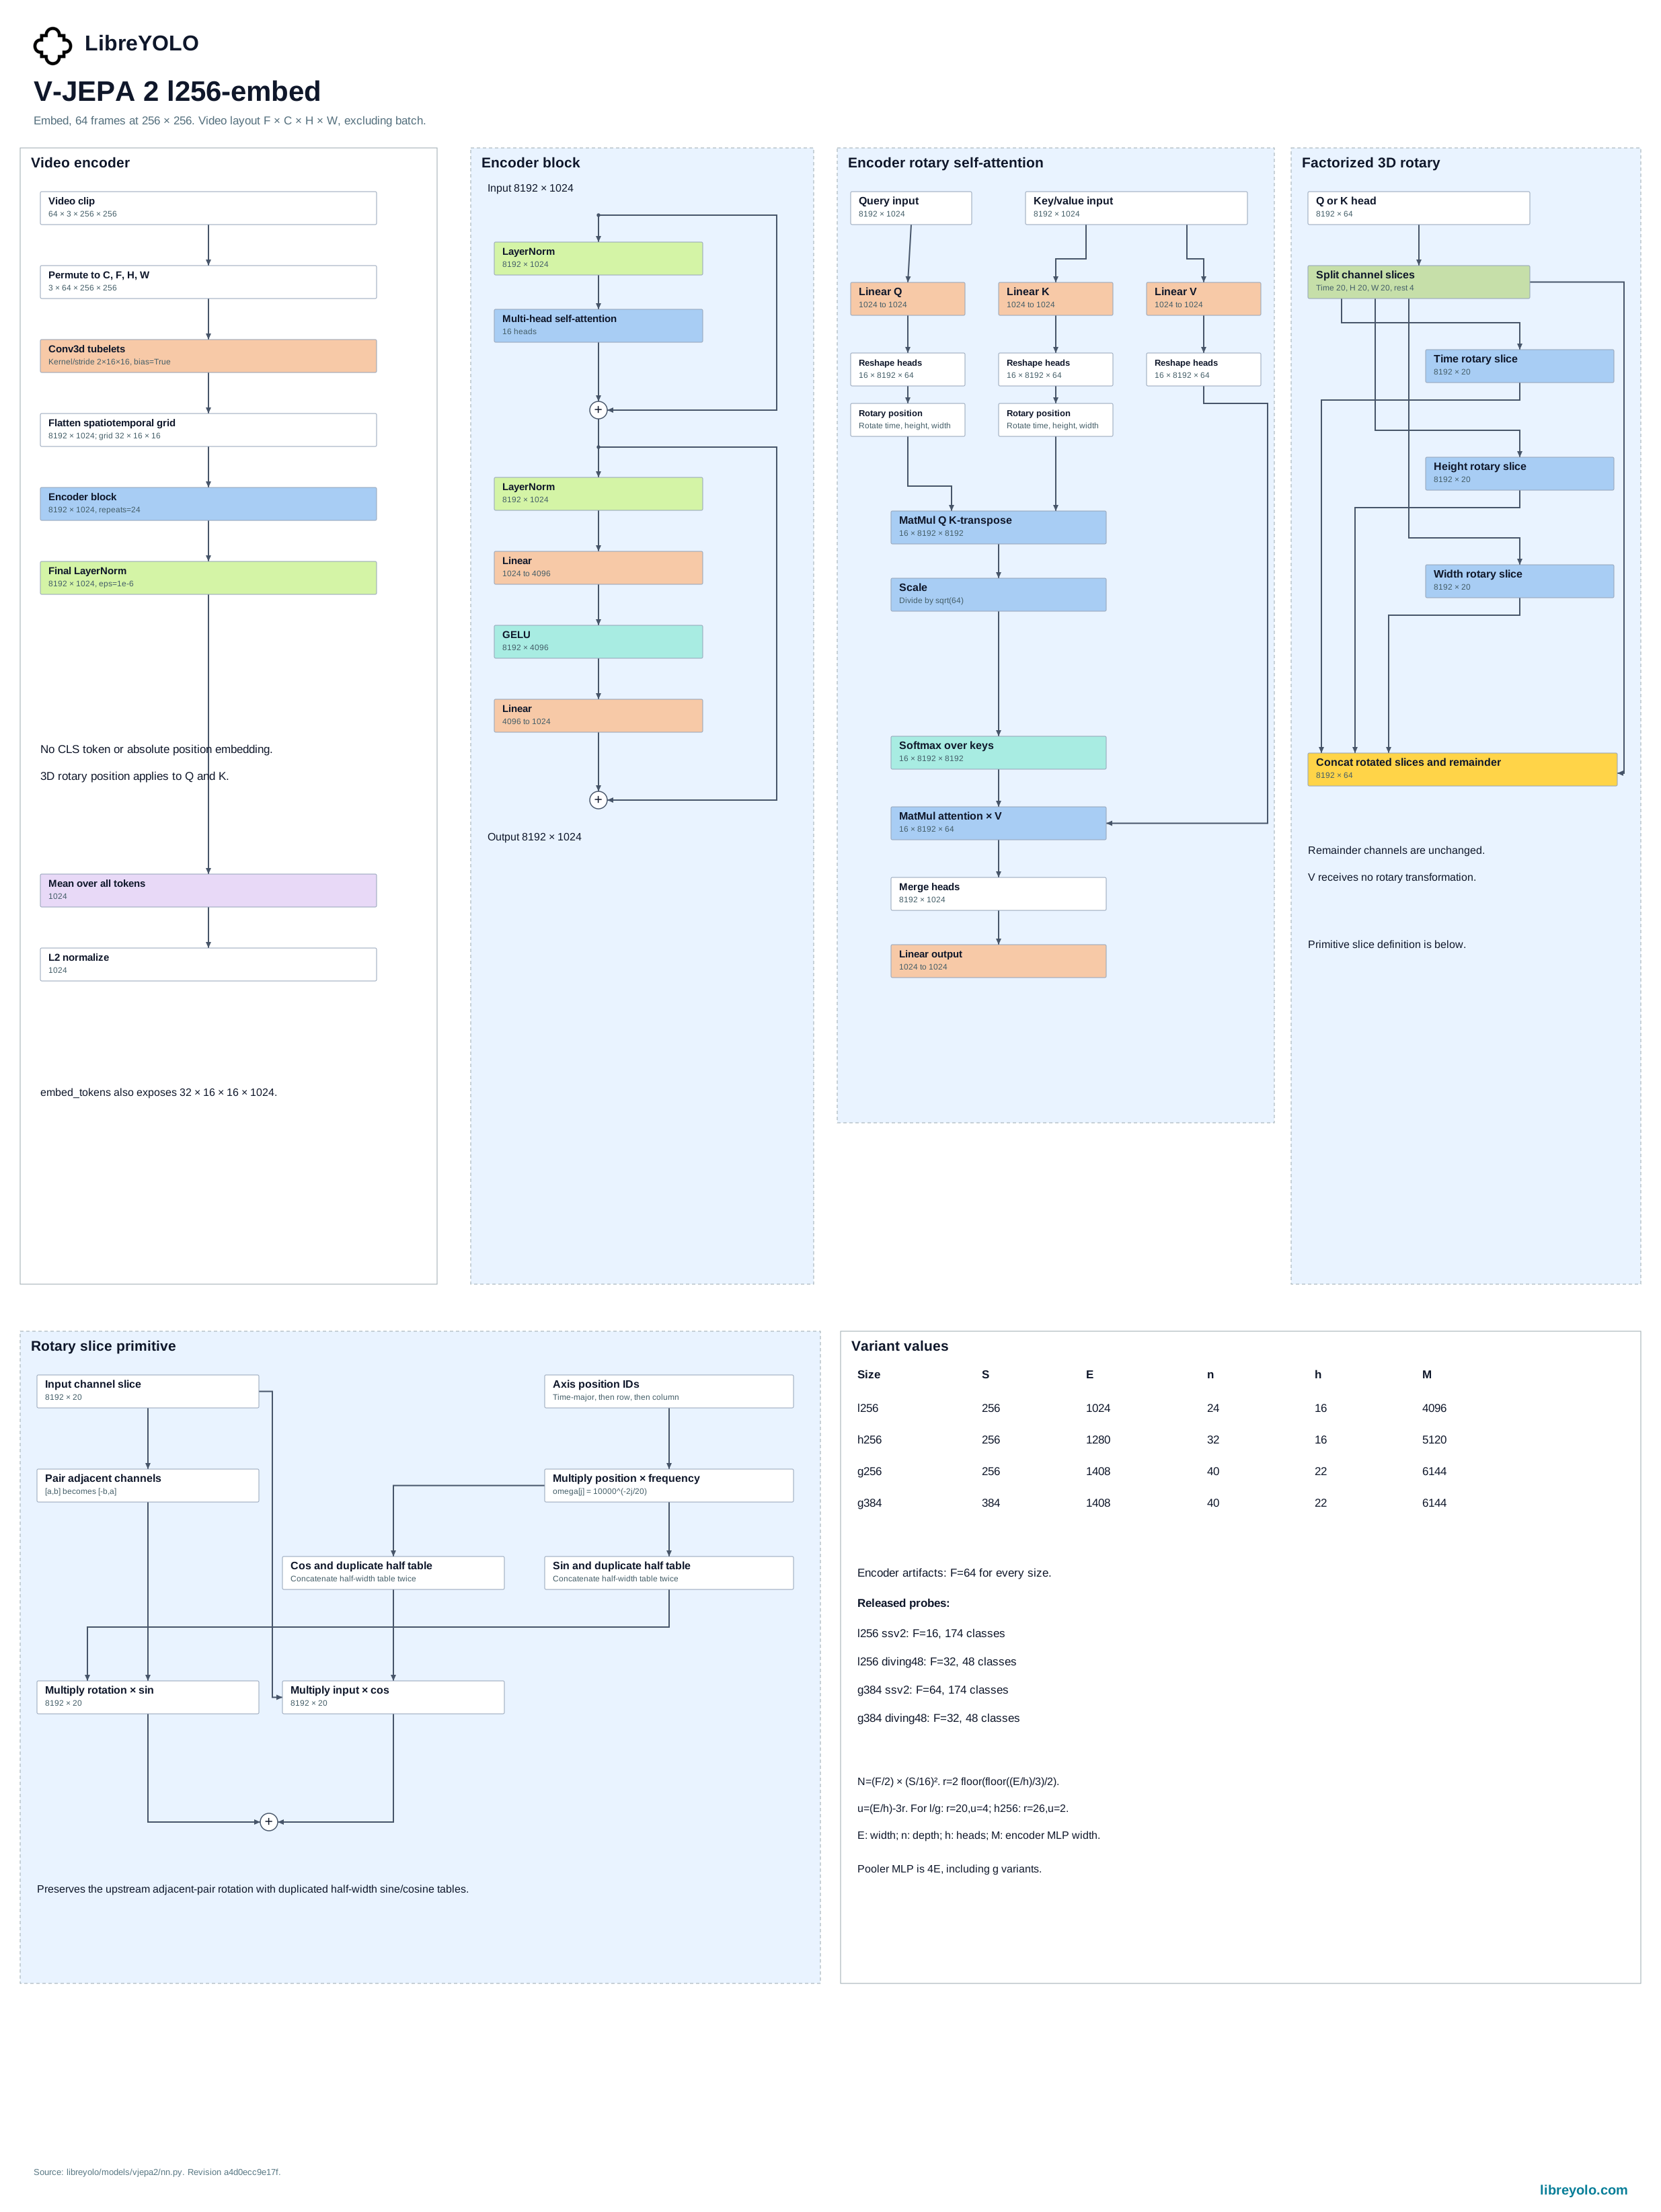
V-JEPA 2
V-JEPA 2 produces video embeddings and supports training an attentive classification probe.
- Tareas
- embeddings, classification
- Tamaños
- l256, h256, g256, g384 at 256 to 384 px
- Instalación
pip install libreyolo- Nivel de compatibilidad
- Compatible, desde v1.6.0. Modelos entrenables de apoyo: se mantienen operativos en CI y reciben funciones cuando surge la oportunidad.
- Licencias
- Código MIT, pesos MIT; Apache-2.0 for giant encoder artifacts. Uso comercial
Install
pip install "libreyolo"Predict
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibreVJEPA2l256-embed.pt", device="cpu")result = model(SAMPLE_IMAGE)print(result.embeddings)tokens = model.embed_tokens(SAMPLE_IMAGE)print(tokens.shape)A still image is promoted to a clip. embed_tokens() returns (B, T, H, W, D) tokens; the public embedding normalizes their mean. Exported clip graphs require direct five-dimensional runtime input.
Train
Only the attentive probe and linear classifier train; the encoder stays frozen. Use the classification task and a video-manifest dataset. Defaults are 10 epochs, batch 2, learning rate 0.001 and workers 0. Full encoder fine-tuning and pretraining are not supported.
Dataset setup describes the required training data.
from libreyolo import LibreYOLO model = LibreYOLO("LibreVJEPA2l256-cls-ssv2.pt", device="cpu")# Replace with your video dataset YAML (train/val manifests of '<video-path> <class-id>' lines).model.train(data="path/to/your/video_dataset.yaml", epochs=1, device="cpu", workers=0)Validate
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibreVJEPA2l256-cls-ssv2.pt", device="cpu")# Replace with your video dataset YAML; val() reads its val manifest of '<video-path> <class-id>' lines.metrics = model.val(data="path/to/your/video_dataset.yaml", workers=0)print(metrics)Use the dataset format for this task. Validation explains the dataset requirements and returned metrics.
Export
| Tarea | ONNX | TorchScript | ExecuTorch | TensorRT | OpenVINO | Paddle | MNN | RKNN | ncnn | TFLite | CoreML | Core AI |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Embeddings | Embeddings to ONNX: compatible | Embeddings to TorchScript: compatible | Embeddings to ExecuTorch: compatible | Embeddings to TensorRT: compatible | Embeddings to OpenVINO: compatible | Embeddings to Paddle: no compatible | Embeddings to MNN: no compatible | Embeddings to RKNN: no compatible | Embeddings to ncnn: no compatible | Embeddings to TFLite: no compatible | Embeddings to CoreML: no compatible | Embeddings to Core AI: no compatible |
| Classification | Classification to ONNX: compatible | Classification to TorchScript: compatible | Classification to ExecuTorch: compatible | Classification to TensorRT: compatible | Classification to OpenVINO: compatible | Classification to Paddle: no compatible | Classification to MNN: no compatible | Classification to RKNN: no compatible | Classification to ncnn: no compatible | Classification to TFLite: no compatible | Classification to CoreML: no compatible | Classification to Core AI: no compatible |
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibreVJEPA2l256-embed.pt", device="cpu")model.export(format="onnx")Export setup lists format dependencies and loading exported artifacts.
Checkpoints
| Archivo | Licencia de los pesos |
|---|---|
| Embeddings | |
| LibreVJEPA2h256-embed.pt | mit |
| LibreVJEPA2l256-embed.pt | mit |
| LibreVJEPA2g384-embed.pt | apache-2.0 |
| LibreVJEPA2g256-embed.pt | apache-2.0 |
| Classification | |
| LibreVJEPA2l256-cls-ssv2.pt | mit |
| LibreVJEPA2l256-cls-diving48.pt | mit |
| LibreVJEPA2g384-cls-diving48.pt | mit |
| LibreVJEPA2g384-cls-ssv2.pt | mit |
Todos los archivos anteriores existen hoy en la organización de LibreYOLO y se descargan la primera vez que se usan.
Licensing
Comprueba la licencia en el repositorio de Hugging Face de los pesos concretos que descargues. Cada checkpoint de la organización de LibreYOLO incluye una, y no siempre es la misma en toda una familia. Ese repositorio es la fuente autorizada; el resumen siguiente describe qué se aplicaba cuando se verificó esta página por última vez.
Esta es una descripción de las licencias implicadas, no asesoramiento legal. Si la respuesta es importante a nivel comercial, lee las licencias y busca tu propio asesoramiento.
- Trabajo original
- V-JEPA 2, Meta AI
- Licencia del proyecto original
- MIT; Apache-2.0 for giant encoder artifacts
- Fuente del proyecto original
- github.com/facebookresearch/vjepa2
- Código de LibreYOLO
- MIT
- Pesos
- MIT; Apache-2.0 for giant encoder artifacts, republicados en huggingface.co/LibreYOLO
- Interpretación
- Licenses differ by artifact: the two giant encoder artifacts are Apache-2.0; the other mirrored encoders and classification probes are MIT.