ShowUI
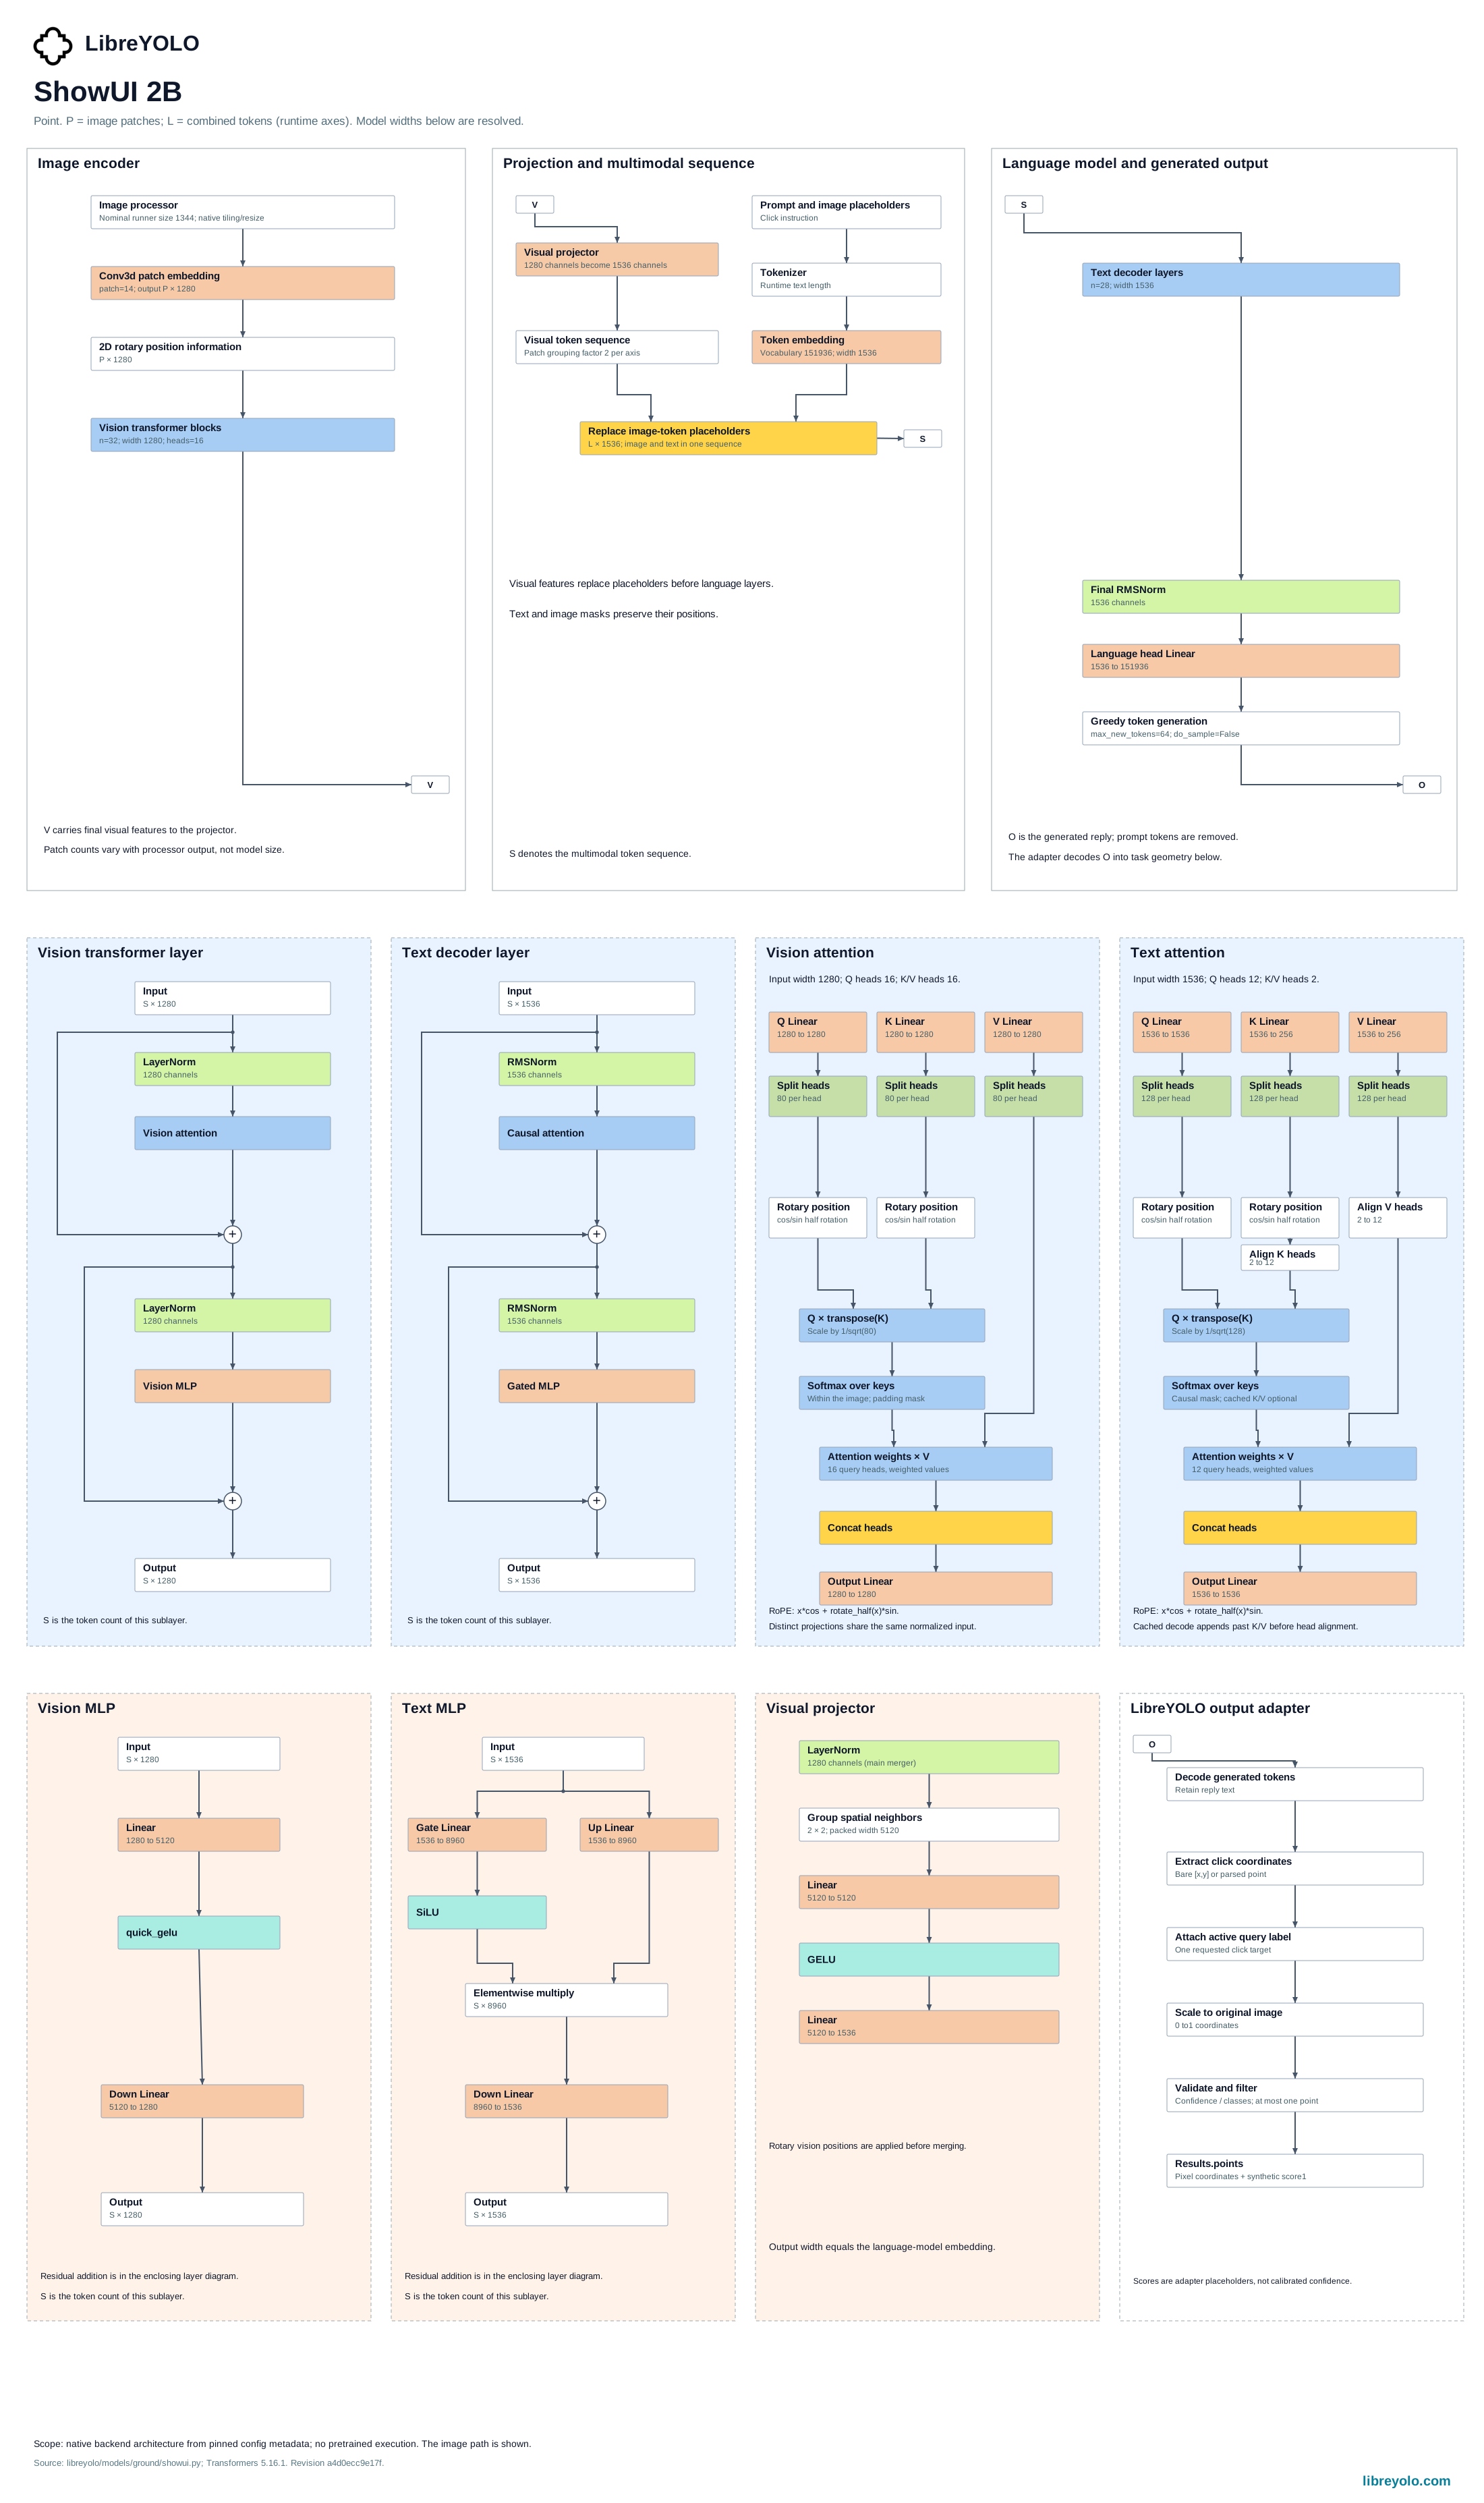
ShowUI locates the target of an instruction as an image point.
- 작업
- point detection
- 크기
- 2b at 1344 px
- 설치
pip install "libreyolo[vlm]"- 지원 티어
- 별도 티어, v1.6.0부터 지원. 자체 팩토리와 계약을 갖춘 별도의 제품 영역입니다.
- 라이선스
- 코드 MIT, 가중치 MIT. 상업적 사용
Install
bash
pip install "libreyolo[ground]"Predict
Python
from libreyolo import LibreGround, SAMPLE_IMAGE model = LibreGround("showui-2b", device="cpu")result = model(SAMPLE_IMAGE, prompt="the person")print(result.points.xy)Use prompt= or query= for one call, or set_query() for a persistent instruction. A list of instructions on one image returns at most one click per query. Multi-query calls on image lists or folders raise an error. Coordinates refer to the original image. Training, validation and export are not supported. See the grounding API.
Licensing
내려받는 특정 가중치의 Hugging Face 저장소에서 라이선스를 확인하십시오. LibreYOLO 조직의 모든 체크포인트에는 라이선스가 있으며 한 계열 안에서도 항상 같지는 않습니다. 해당 저장소가 신뢰할 수 있는 기준입니다. 아래 요약은 이 페이지를 마지막으로 검증했을 때 적용된 내용을 설명합니다.
관련 라이선스에 관한 설명이며 법률 자문이 아닙니다. 상업적으로 중요한 사안이라면 라이선스를 직접 읽고 별도의 법률 자문을 받으십시오.
- 원작
- ShowUI, ShowUI authors
- 업스트림 라이선스
- MIT
- 업스트림 소스
- github.com/showlab/ShowUI
- LibreYOLO 코드
- MIT
- 가중치
- MIT, 저자가 배포합니다. LibreYOLO는 이를 호스팅하거나 미러링하지 않습니다.
- 해석
- The model publisher declares MIT.
Citation
@misc{lin2024showui,
      title={ShowUI: One Vision-Language-Action Model for GUI Visual Agent},
      author={Kevin Qinghong Lin and Linjie Li and Difei Gao and Zhengyuan Yang and Shiwei Wu and Zechen Bai and Weixian Lei and Lijuan Wang and Mike Zheng Shou},
      year={2024},
      eprint={2411.17465},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2411.17465},
}raw.githubusercontent.com/showlab/ShowUI/main/README.md에 있는 저자의 인용 블록에서 복사했습니다.