V-JEPA 2
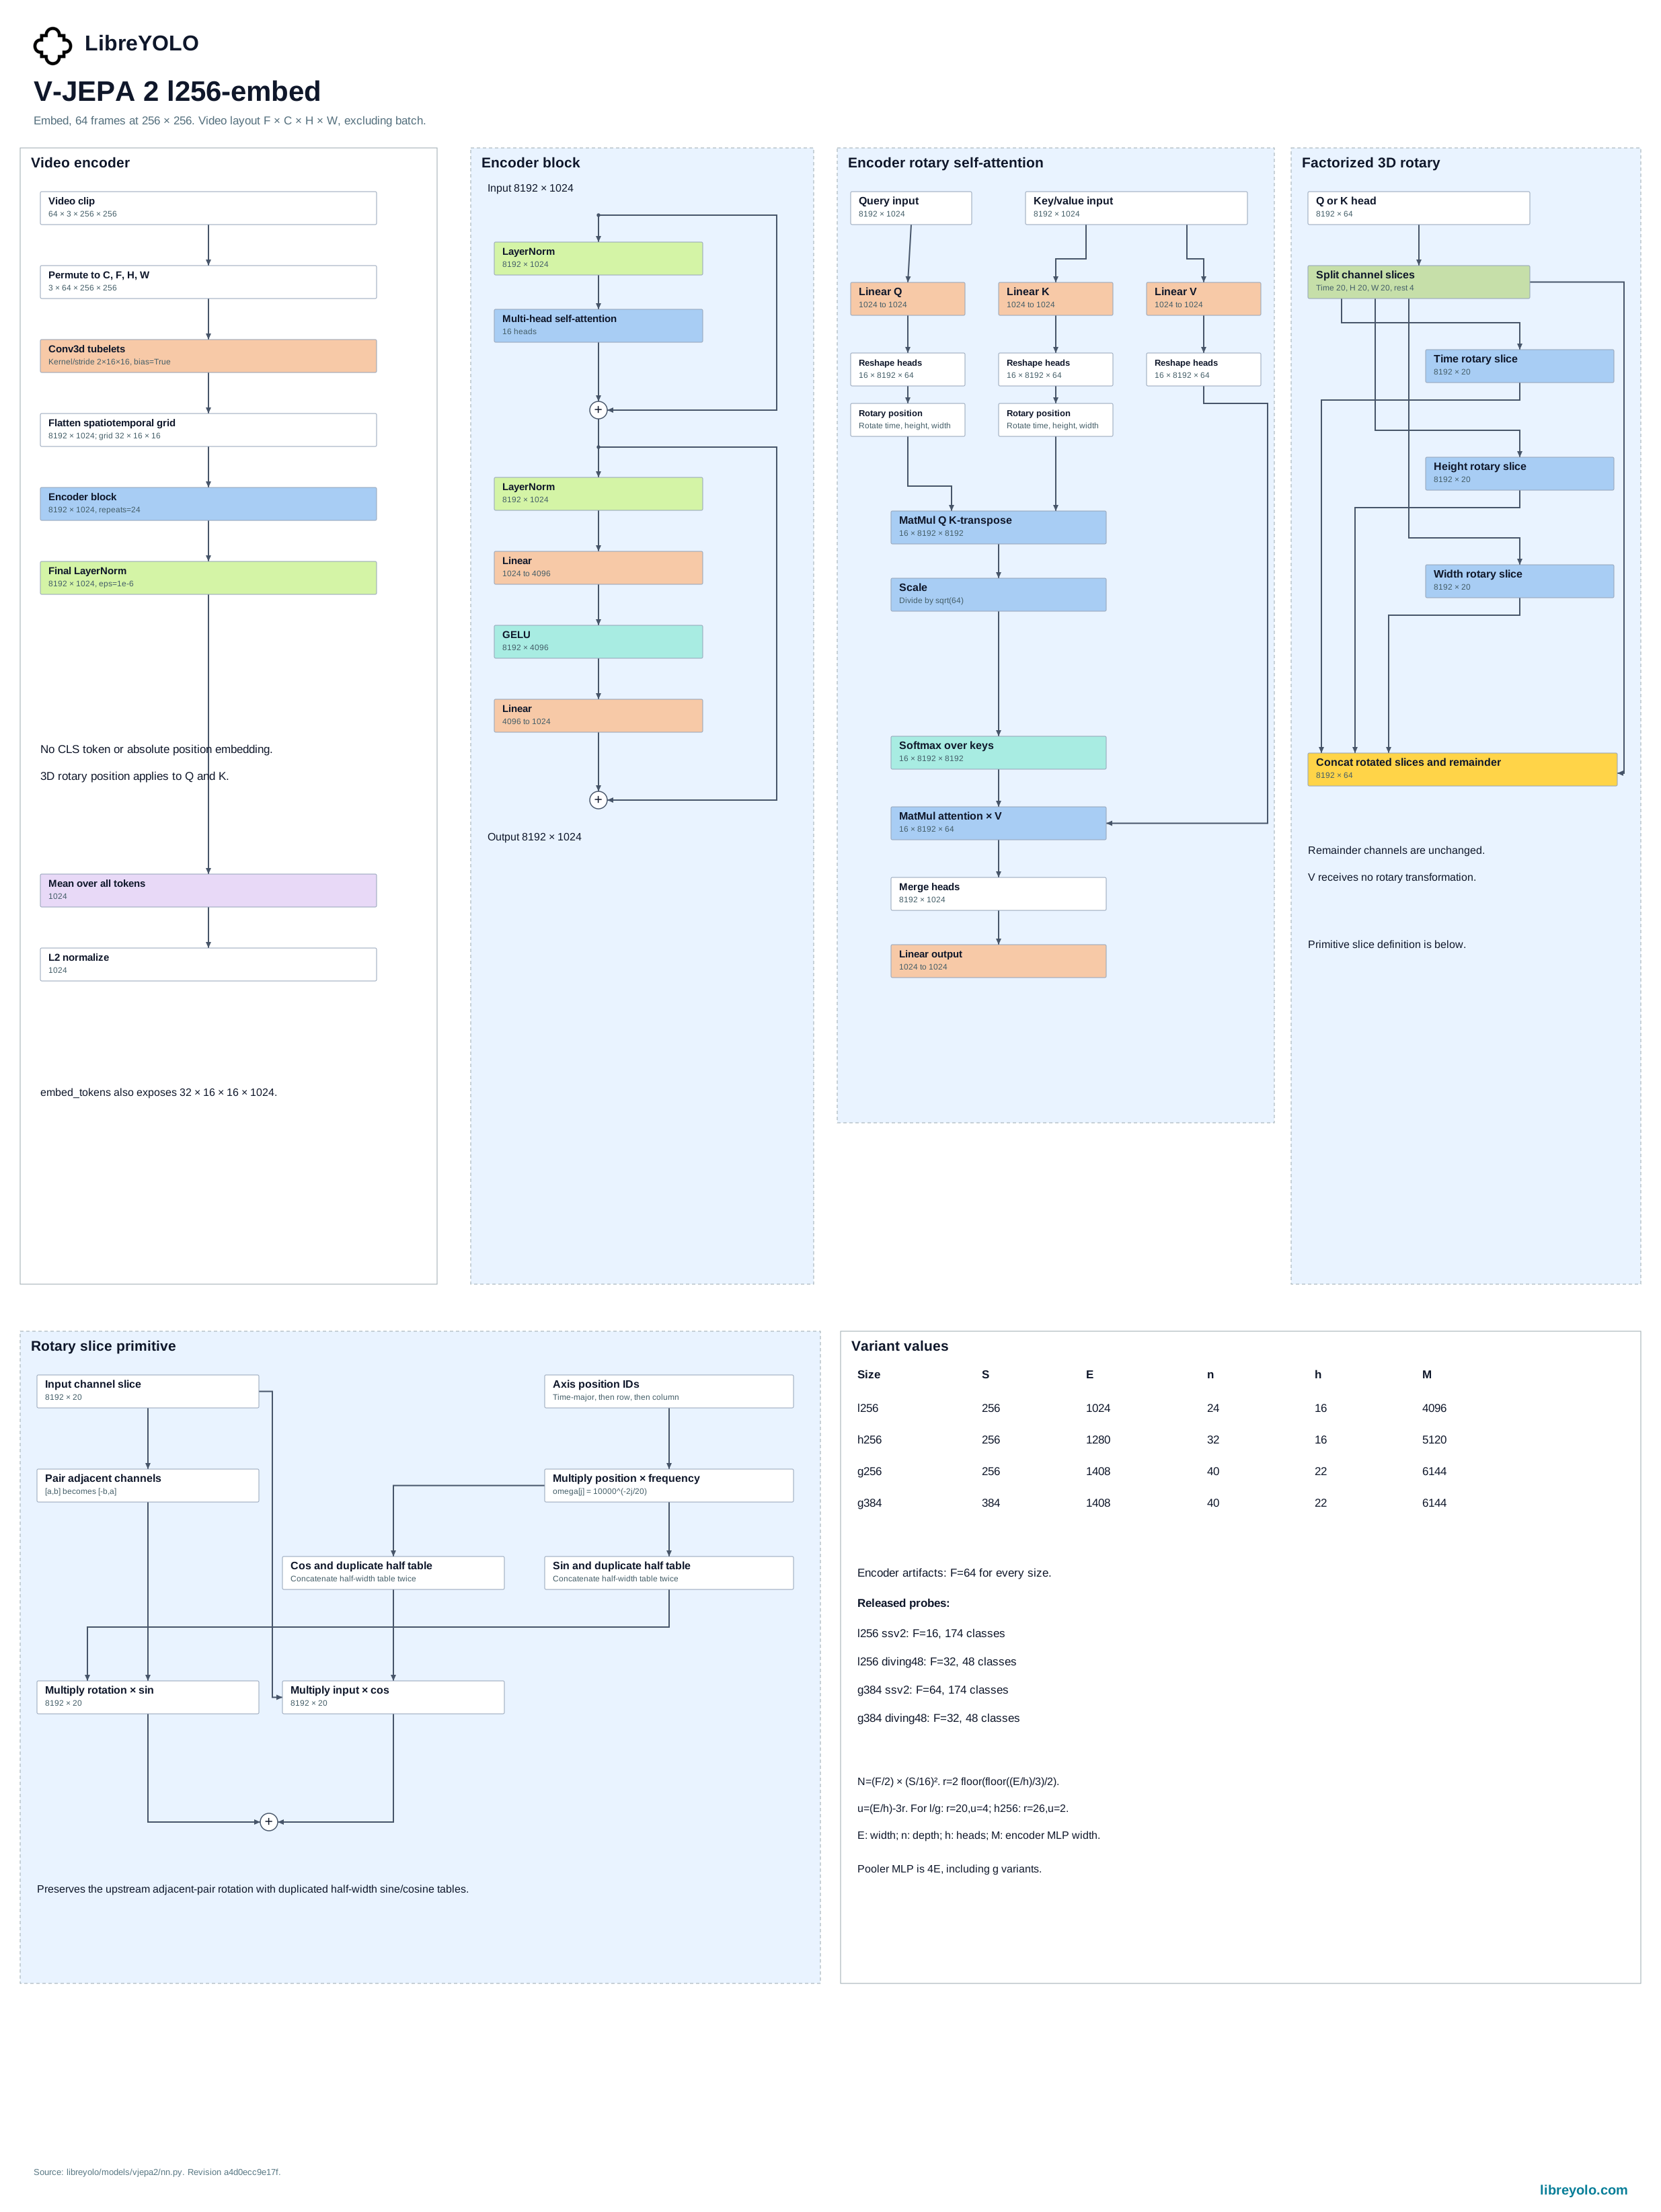
V-JEPA 2 produces video embeddings and supports training an attentive classification probe.
- 작업
- embeddings, classification
- 크기
- l256, h256, g256, g384 at 256 to 384 px
- 설치
pip install libreyolo- 지원 티어
- 지원, v1.6.0부터 지원. 보조 학습 가능 모델입니다. CI 통과 상태를 유지하며 기능은 여건에 따라 추가됩니다.
- 라이선스
- 코드 MIT, 가중치 MIT; Apache-2.0 for giant encoder artifacts. 상업적 사용
Install
pip install "libreyolo"Predict
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibreVJEPA2l256-embed.pt", device="cpu")result = model(SAMPLE_IMAGE)print(result.embeddings)tokens = model.embed_tokens(SAMPLE_IMAGE)print(tokens.shape)A still image is promoted to a clip. embed_tokens() returns (B, T, H, W, D) tokens; the public embedding normalizes their mean. Exported clip graphs require direct five-dimensional runtime input.
Train
Only the attentive probe and linear classifier train; the encoder stays frozen. Use the classification task and a video-manifest dataset. Defaults are 10 epochs, batch 2, learning rate 0.001 and workers 0. Full encoder fine-tuning and pretraining are not supported.
Dataset setup describes the required training data.
from libreyolo import LibreYOLO model = LibreYOLO("LibreVJEPA2l256-cls-ssv2.pt", device="cpu")# Replace with your video dataset YAML (train/val manifests of '<video-path> <class-id>' lines).model.train(data="path/to/your/video_dataset.yaml", epochs=1, device="cpu", workers=0)Validate
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibreVJEPA2l256-cls-ssv2.pt", device="cpu")# Replace with your video dataset YAML; val() reads its val manifest of '<video-path> <class-id>' lines.metrics = model.val(data="path/to/your/video_dataset.yaml", workers=0)print(metrics)Use the dataset format for this task. Validation explains the dataset requirements and returned metrics.
Export
| 작업 | ONNX | TorchScript | ExecuTorch | TensorRT | OpenVINO | Paddle | MNN | RKNN | ncnn | TFLite | CoreML | Core AI |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Embeddings | Embeddings to ONNX: 지원함 | Embeddings to TorchScript: 지원함 | Embeddings to ExecuTorch: 지원함 | Embeddings to TensorRT: 지원함 | Embeddings to OpenVINO: 지원함 | Embeddings to Paddle: 지원하지 않음 | Embeddings to MNN: 지원하지 않음 | Embeddings to RKNN: 지원하지 않음 | Embeddings to ncnn: 지원하지 않음 | Embeddings to TFLite: 지원하지 않음 | Embeddings to CoreML: 지원하지 않음 | Embeddings to Core AI: 지원하지 않음 |
| Classification | Classification to ONNX: 지원함 | Classification to TorchScript: 지원함 | Classification to ExecuTorch: 지원함 | Classification to TensorRT: 지원함 | Classification to OpenVINO: 지원함 | Classification to Paddle: 지원하지 않음 | Classification to MNN: 지원하지 않음 | Classification to RKNN: 지원하지 않음 | Classification to ncnn: 지원하지 않음 | Classification to TFLite: 지원하지 않음 | Classification to CoreML: 지원하지 않음 | Classification to Core AI: 지원하지 않음 |
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibreVJEPA2l256-embed.pt", device="cpu")model.export(format="onnx")Export setup lists format dependencies and loading exported artifacts.
Checkpoints
| 파일 | 가중치 라이선스 |
|---|---|
| Embeddings | |
| LibreVJEPA2h256-embed.pt | mit |
| LibreVJEPA2l256-embed.pt | mit |
| LibreVJEPA2g384-embed.pt | apache-2.0 |
| LibreVJEPA2g256-embed.pt | apache-2.0 |
| Classification | |
| LibreVJEPA2l256-cls-ssv2.pt | mit |
| LibreVJEPA2l256-cls-diving48.pt | mit |
| LibreVJEPA2g384-cls-diving48.pt | mit |
| LibreVJEPA2g384-cls-ssv2.pt | mit |
위의 모든 파일은 현재 LibreYOLO 조직에 있으며 처음 사용할 때 내려받습니다.
Licensing
내려받는 특정 가중치의 Hugging Face 저장소에서 라이선스를 확인하십시오. LibreYOLO 조직의 모든 체크포인트에는 라이선스가 있으며 한 계열 안에서도 항상 같지는 않습니다. 해당 저장소가 신뢰할 수 있는 기준입니다. 아래 요약은 이 페이지를 마지막으로 검증했을 때 적용된 내용을 설명합니다.
관련 라이선스에 관한 설명이며 법률 자문이 아닙니다. 상업적으로 중요한 사안이라면 라이선스를 직접 읽고 별도의 법률 자문을 받으십시오.
- 원작
- V-JEPA 2, Meta AI
- 업스트림 라이선스
- MIT; Apache-2.0 for giant encoder artifacts
- LibreYOLO 코드
- MIT
- 가중치
- MIT; Apache-2.0 for giant encoder artifacts, huggingface.co/LibreYOLO에 다시 게시됨
- 해석
- Licenses differ by artifact: the two giant encoder artifacts are Apache-2.0; the other mirrored encoders and classification probes are MIT.