Perception Encoder
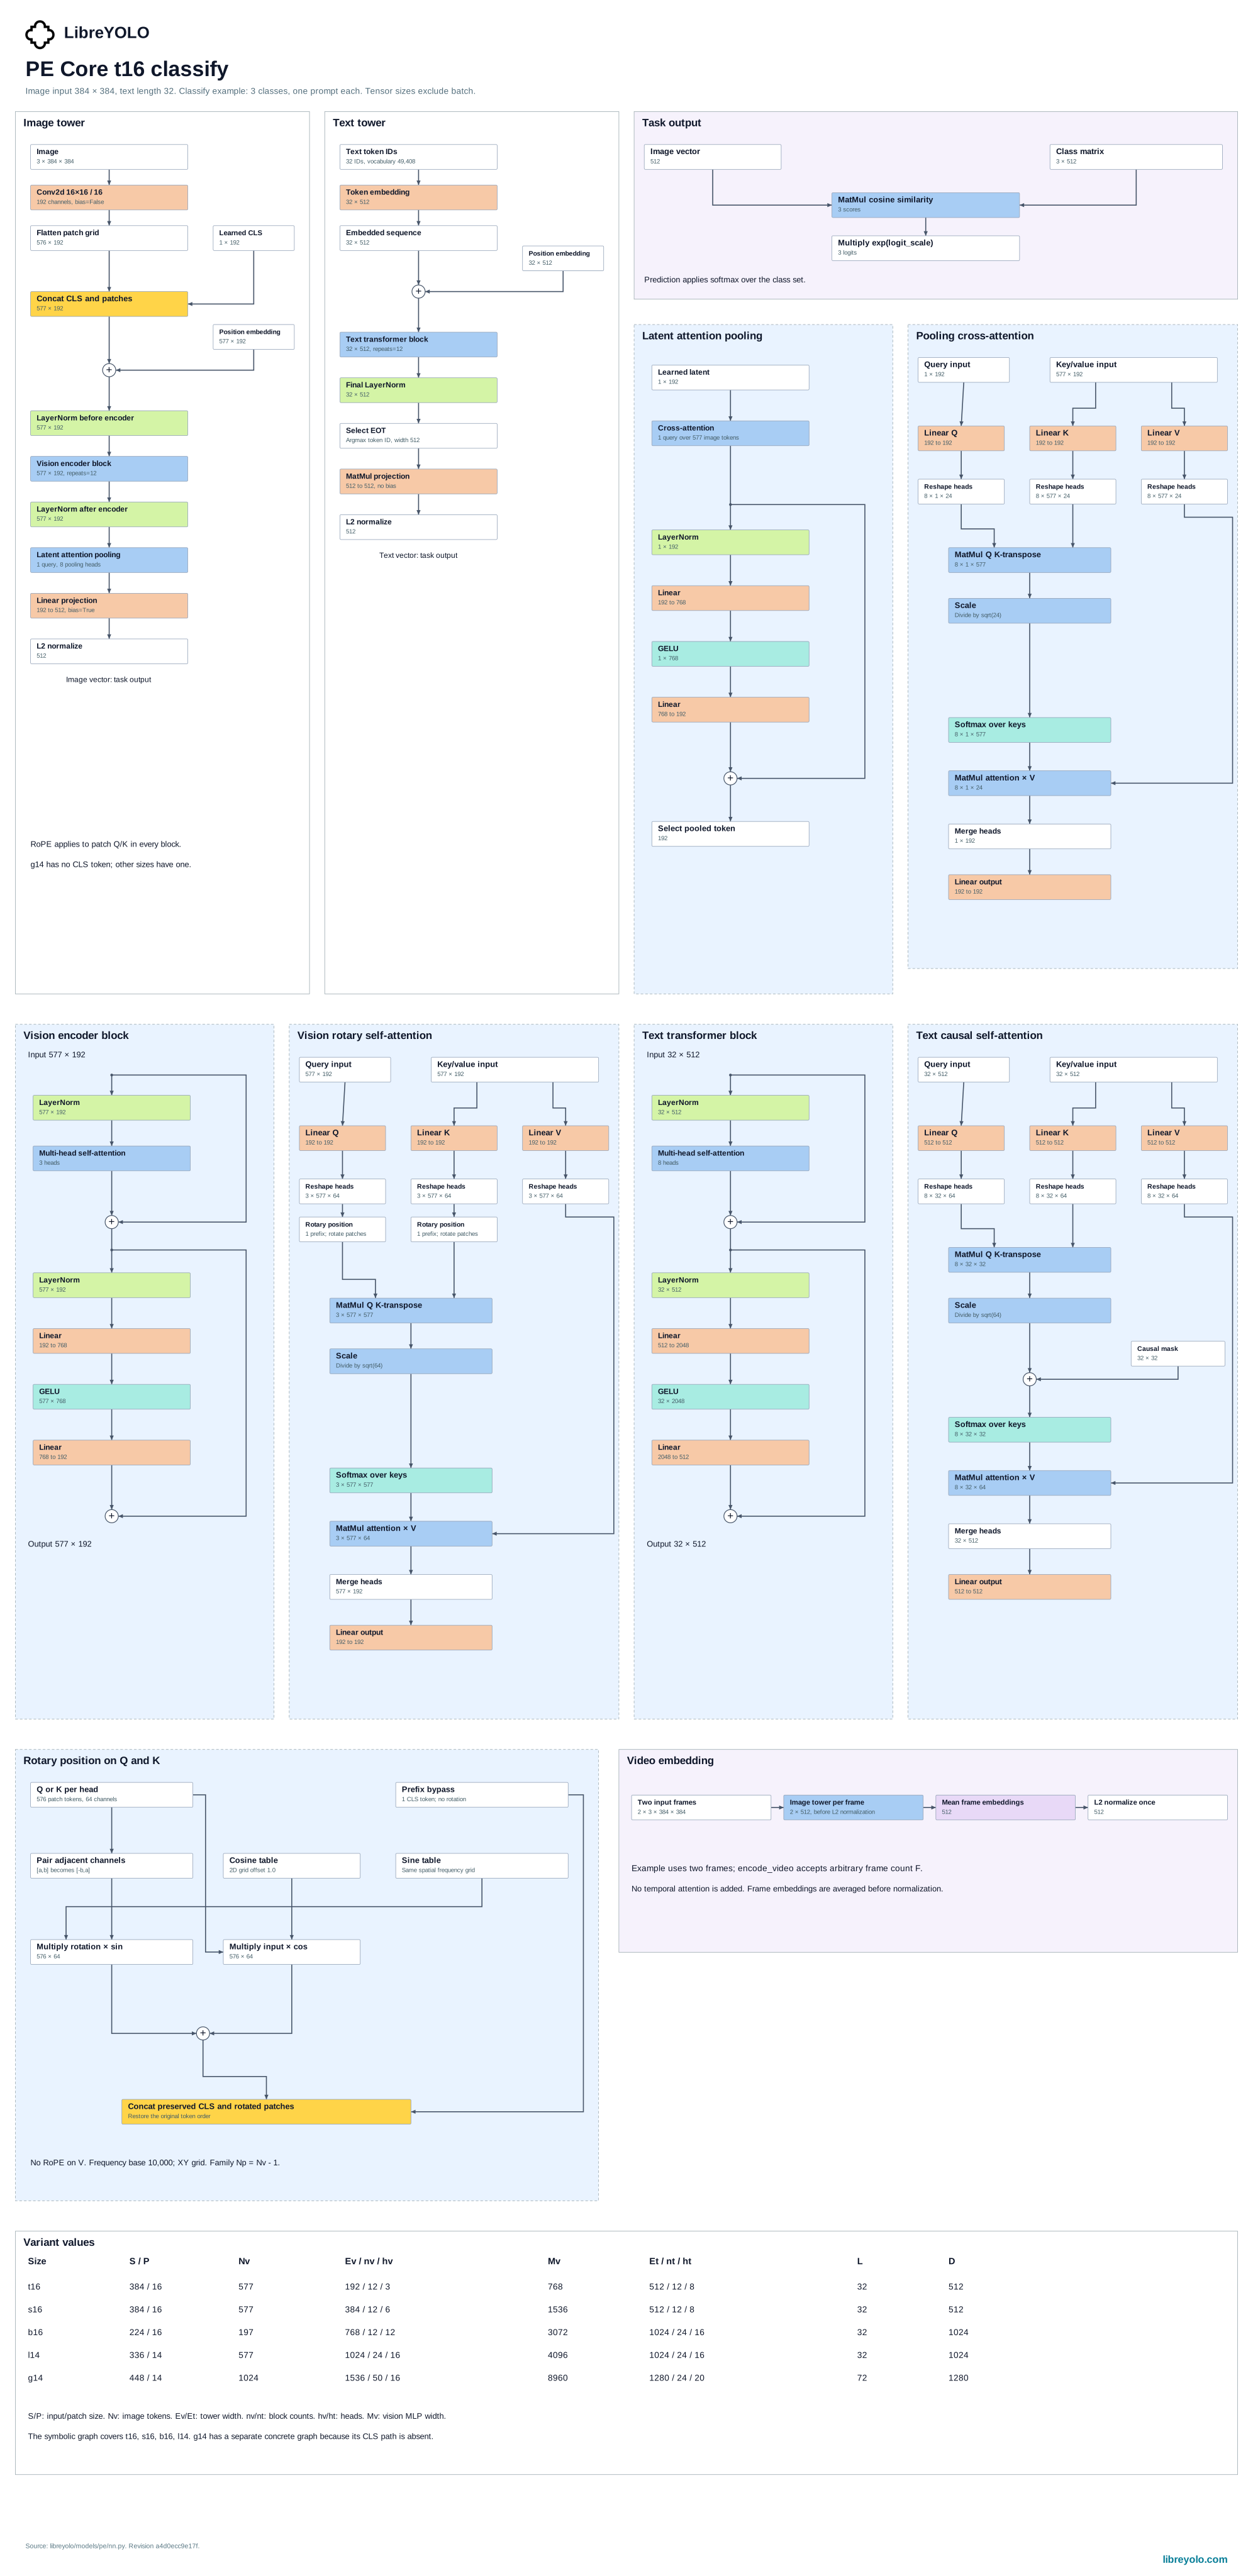
Perception Encoder maps images, text and finite video clips into a shared embedding space.
- Zadania
- classification, embeddings
- Instalacja
pip install "libreyolo[clip]"- Poziom obsługi
- Poziom siostrzany, od wersji v1.6.0. Osobna część produktu z własną fabryką i kontraktem.
- Projekt źródłowy
- Perception Encoder, autorzy: Meta AI, licencja: Apache-2.0. Publikacja, kod źródłowy
- Licencje
- Kod: MIT, wagi: Apache-2.0. Użycie komercyjne
Install
pip install "libreyolo[clip]"Predict
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibrePEt16-cls.pt", device="cpu")model.set_classes(["person", "building"])result = model(SAMPLE_IMAGE)print(result.probs)Set classes before zero-shot classification. Select task="embed" when loading for embeddings. Video embedding samples clip_frames=8 frames by default, averages their vectors and L2-normalizes the result. Training is not supported. Exported video graphs take direct runtime input.
Export
| Zadanie | ONNX | TorchScript | ExecuTorch | TensorRT | OpenVINO | Paddle | MNN | RKNN | ncnn | TFLite | CoreML | Core AI |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Classification | Classification to ONNX: obsługiwane | Classification to TorchScript: obsługiwane | Classification to ExecuTorch: obsługiwane | Classification to TensorRT: obsługiwane | Classification to OpenVINO: obsługiwane | Classification to Paddle: brak obsługi | Classification to MNN: brak obsługi | Classification to RKNN: brak obsługi | Classification to ncnn: brak obsługi | Classification to TFLite: brak obsługi | Classification to CoreML: brak obsługi | Classification to Core AI: brak obsługi |
| Embeddings | Embeddings to ONNX: obsługiwane | Embeddings to TorchScript: obsługiwane | Embeddings to ExecuTorch: obsługiwane | Embeddings to TensorRT: obsługiwane | Embeddings to OpenVINO: obsługiwane | Embeddings to Paddle: brak obsługi | Embeddings to MNN: brak obsługi | Embeddings to RKNN: brak obsługi | Embeddings to ncnn: brak obsługi | Embeddings to TFLite: brak obsługi | Embeddings to CoreML: brak obsługi | Embeddings to Core AI: brak obsługi |
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibrePEt16-cls.pt", device="cpu")model.export(format="onnx")Export setup lists format dependencies and loading exported artifacts.
Checkpoints
| Plik | Licencja wag |
|---|---|
| Classification | |
| LibrePEt16-cls.pt | apache-2.0 |
| LibrePEs16-cls.pt | apache-2.0 |
| LibrePEb16-cls.pt | apache-2.0 |
| LibrePEl14-cls.pt | apache-2.0 |
| LibrePEg14-cls.pt | apache-2.0 |
Każdy z powyższych plików jest obecnie dostępny w organizacji LibreYOLO i pobierany przy pierwszym użyciu.
Licensing
Sprawdź licencję w repozytorium konkretnych pobieranych wag na Hugging Face. Każdy checkpoint w organizacji LibreYOLO ma licencję, która nie zawsze jest taka sama w całej rodzinie. To repozytorium jest źródłem rozstrzygającym, a poniższe podsumowanie opisuje stan z chwili ostatniej weryfikacji tej strony.
To opis obowiązujących licencji, a nie porada prawna. Jeśli odpowiedź ma znaczenie komercyjne, przeczytaj licencje i zasięgnij własnej porady prawnej.
- Oryginalna praca
- Perception Encoder, Meta AI
- Licencja projektu źródłowego
- Apache-2.0
- Kod źródłowy projektu
- github.com/facebookresearch/perception_models
- Kod LibreYOLO
- MIT
- Wagi
- Apache-2.0, ponownie opublikowane w huggingface.co/LibreYOLO
- Interpretacja
- The publisher declares Apache-2.0 for the encoder weights.
Citation
@article{bolya2025PerceptionEncoder,
  title={Perception Encoder: The best visual embeddings are not at the output of the network},
  author={Daniel Bolya and Po-Yao Huang and Peize Sun and Jang Hyun Cho and Andrea Madotto and Chen Wei and Tengyu Ma and Jiale Zhi and Jathushan Rajasegaran and Hanoona Rasheed and Junke Wang and Marco Monteiro and Hu Xu and Shiyu Dong and Nikhila Ravi and Daniel Li and Piotr Doll{\'a}r and Christoph Feichtenhofer},
  journal={arXiv:2504.13181},
  year={2025}
}
Skopiowano z bloku cytowania autorów w raw.githubusercontent.com/facebookresearch/perception_models/main/README.md.