V-JEPA 2
V-JEPA 2 produces video embeddings and supports training an attentive classification probe.
- Zadania
- embeddings, classification
- Rozmiary
- l256, h256, g256, g384 at 256 to 384 px
- Instalacja
pip install libreyolo- Poziom obsługi
- Obsługiwany, od wersji v1.6.0. Dodatkowe trenowalne modele: testy CI pozostają zielone, a funkcje są dodawane w miarę możliwości.
- Licencje
- Kod: MIT, wagi: MIT; Apache-2.0 for giant encoder artifacts. Użycie komercyjne
Install
pip install "libreyolo"Predict
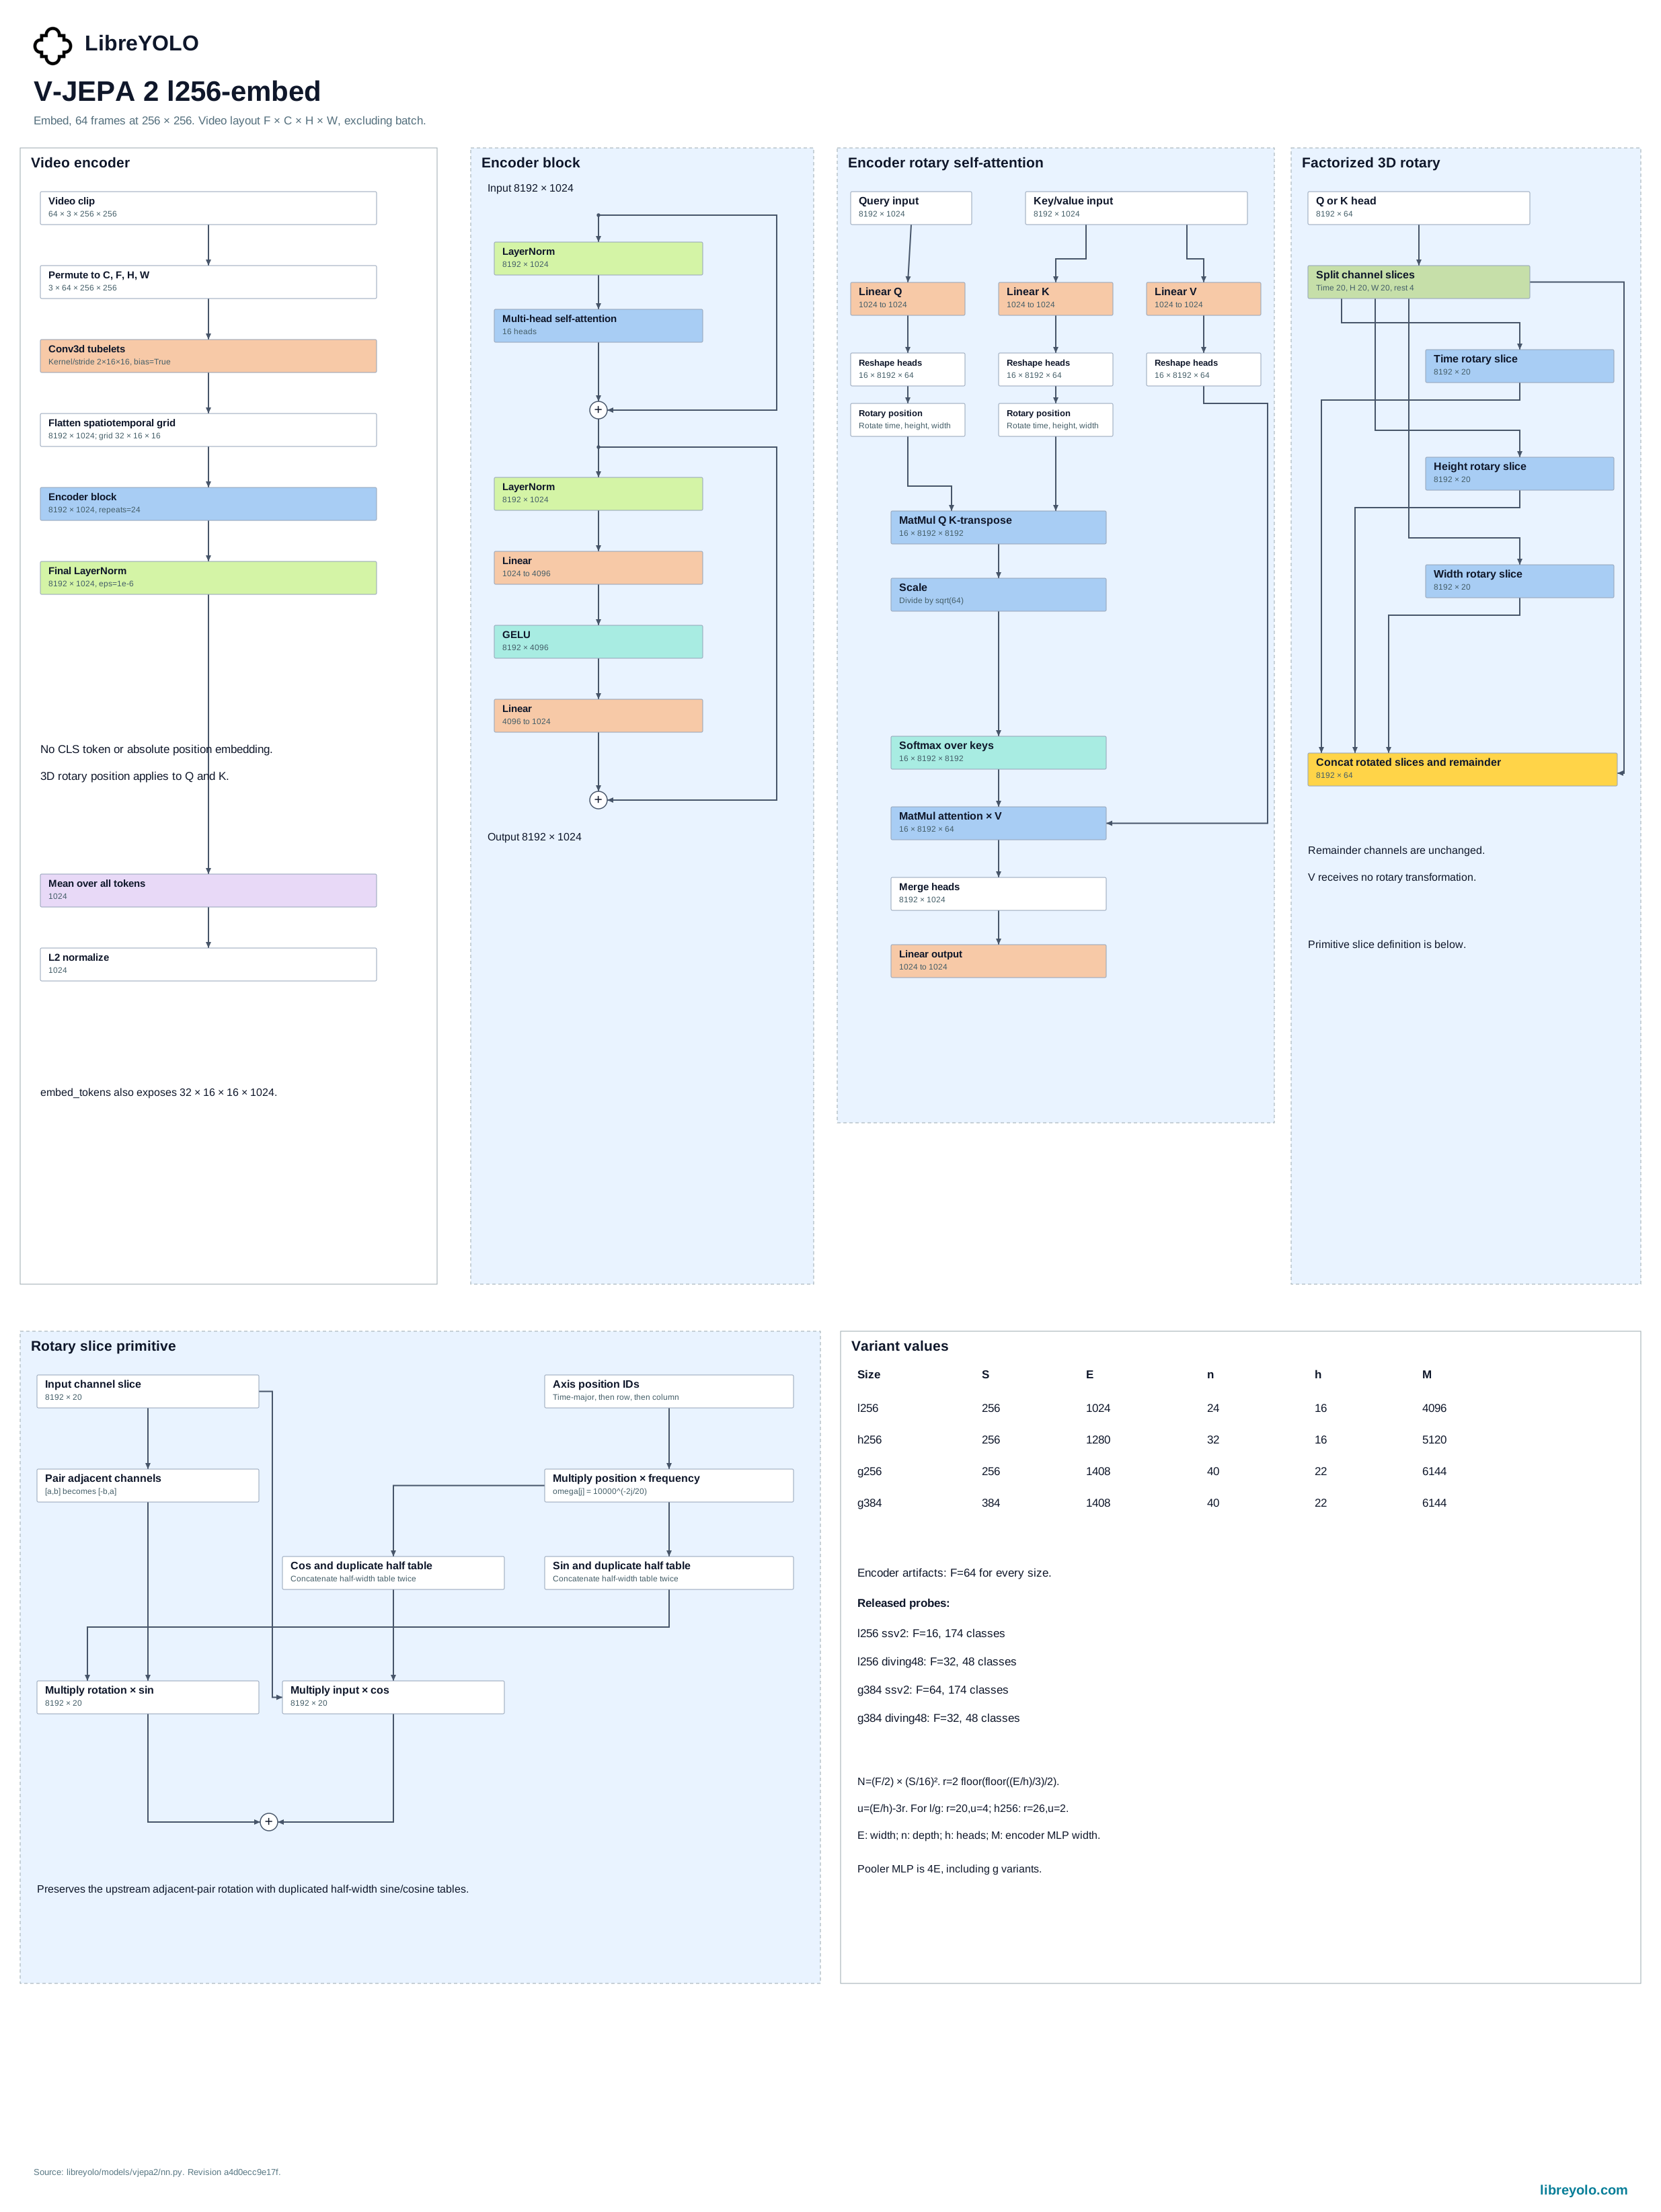
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibreVJEPA2l256-embed.pt", device="cpu")result = model(SAMPLE_IMAGE)print(result.embeddings)tokens = model.embed_tokens(SAMPLE_IMAGE)print(tokens.shape)A still image is promoted to a clip. embed_tokens() returns (B, T, H, W, D) tokens; the public embedding normalizes their mean. Exported clip graphs require direct five-dimensional runtime input.
Train
Only the attentive probe and linear classifier train; the encoder stays frozen. Use the classification task and a video-manifest dataset. Defaults are 10 epochs, batch 2, learning rate 0.001 and workers 0. Full encoder fine-tuning and pretraining are not supported.
Dataset setup describes the required training data.
from libreyolo import LibreYOLO model = LibreYOLO("LibreVJEPA2l256-cls-ssv2.pt", device="cpu")# Replace with your video dataset YAML (train/val manifests of '<video-path> <class-id>' lines).model.train(data="path/to/your/video_dataset.yaml", epochs=1, device="cpu", workers=0)Validate
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibreVJEPA2l256-cls-ssv2.pt", device="cpu")# Replace with your video dataset YAML; val() reads its val manifest of '<video-path> <class-id>' lines.metrics = model.val(data="path/to/your/video_dataset.yaml", workers=0)print(metrics)Use the dataset format for this task. Validation explains the dataset requirements and returned metrics.
Export
| Zadanie | ONNX | TorchScript | ExecuTorch | TensorRT | OpenVINO | Paddle | MNN | RKNN | ncnn | TFLite | CoreML | Core AI |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Embeddings | Embeddings to ONNX: obsługiwane | Embeddings to TorchScript: obsługiwane | Embeddings to ExecuTorch: obsługiwane | Embeddings to TensorRT: obsługiwane | Embeddings to OpenVINO: obsługiwane | Embeddings to Paddle: brak obsługi | Embeddings to MNN: brak obsługi | Embeddings to RKNN: brak obsługi | Embeddings to ncnn: brak obsługi | Embeddings to TFLite: brak obsługi | Embeddings to CoreML: brak obsługi | Embeddings to Core AI: brak obsługi |
| Classification | Classification to ONNX: obsługiwane | Classification to TorchScript: obsługiwane | Classification to ExecuTorch: obsługiwane | Classification to TensorRT: obsługiwane | Classification to OpenVINO: obsługiwane | Classification to Paddle: brak obsługi | Classification to MNN: brak obsługi | Classification to RKNN: brak obsługi | Classification to ncnn: brak obsługi | Classification to TFLite: brak obsługi | Classification to CoreML: brak obsługi | Classification to Core AI: brak obsługi |
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibreVJEPA2l256-embed.pt", device="cpu")model.export(format="onnx")Export setup lists format dependencies and loading exported artifacts.
Checkpoints
| Plik | Licencja wag |
|---|---|
| Embeddings | |
| LibreVJEPA2h256-embed.pt | mit |
| LibreVJEPA2l256-embed.pt | mit |
| LibreVJEPA2g384-embed.pt | apache-2.0 |
| LibreVJEPA2g256-embed.pt | apache-2.0 |
| Classification | |
| LibreVJEPA2l256-cls-ssv2.pt | mit |
| LibreVJEPA2l256-cls-diving48.pt | mit |
| LibreVJEPA2g384-cls-diving48.pt | mit |
| LibreVJEPA2g384-cls-ssv2.pt | mit |
Każdy z powyższych plików jest obecnie dostępny w organizacji LibreYOLO i pobierany przy pierwszym użyciu.
Licensing
Sprawdź licencję w repozytorium konkretnych pobieranych wag na Hugging Face. Każdy checkpoint w organizacji LibreYOLO ma licencję, która nie zawsze jest taka sama w całej rodzinie. To repozytorium jest źródłem rozstrzygającym, a poniższe podsumowanie opisuje stan z chwili ostatniej weryfikacji tej strony.
To opis obowiązujących licencji, a nie porada prawna. Jeśli odpowiedź ma znaczenie komercyjne, przeczytaj licencje i zasięgnij własnej porady prawnej.
- Oryginalna praca
- V-JEPA 2, Meta AI
- Licencja projektu źródłowego
- MIT; Apache-2.0 for giant encoder artifacts
- Kod źródłowy projektu
- github.com/facebookresearch/vjepa2
- Kod LibreYOLO
- MIT
- Wagi
- MIT; Apache-2.0 for giant encoder artifacts, ponownie opublikowane w huggingface.co/LibreYOLO
- Interpretacja
- Licenses differ by artifact: the two giant encoder artifacts are Apache-2.0; the other mirrored encoders and classification probes are MIT.