Perception Encoder
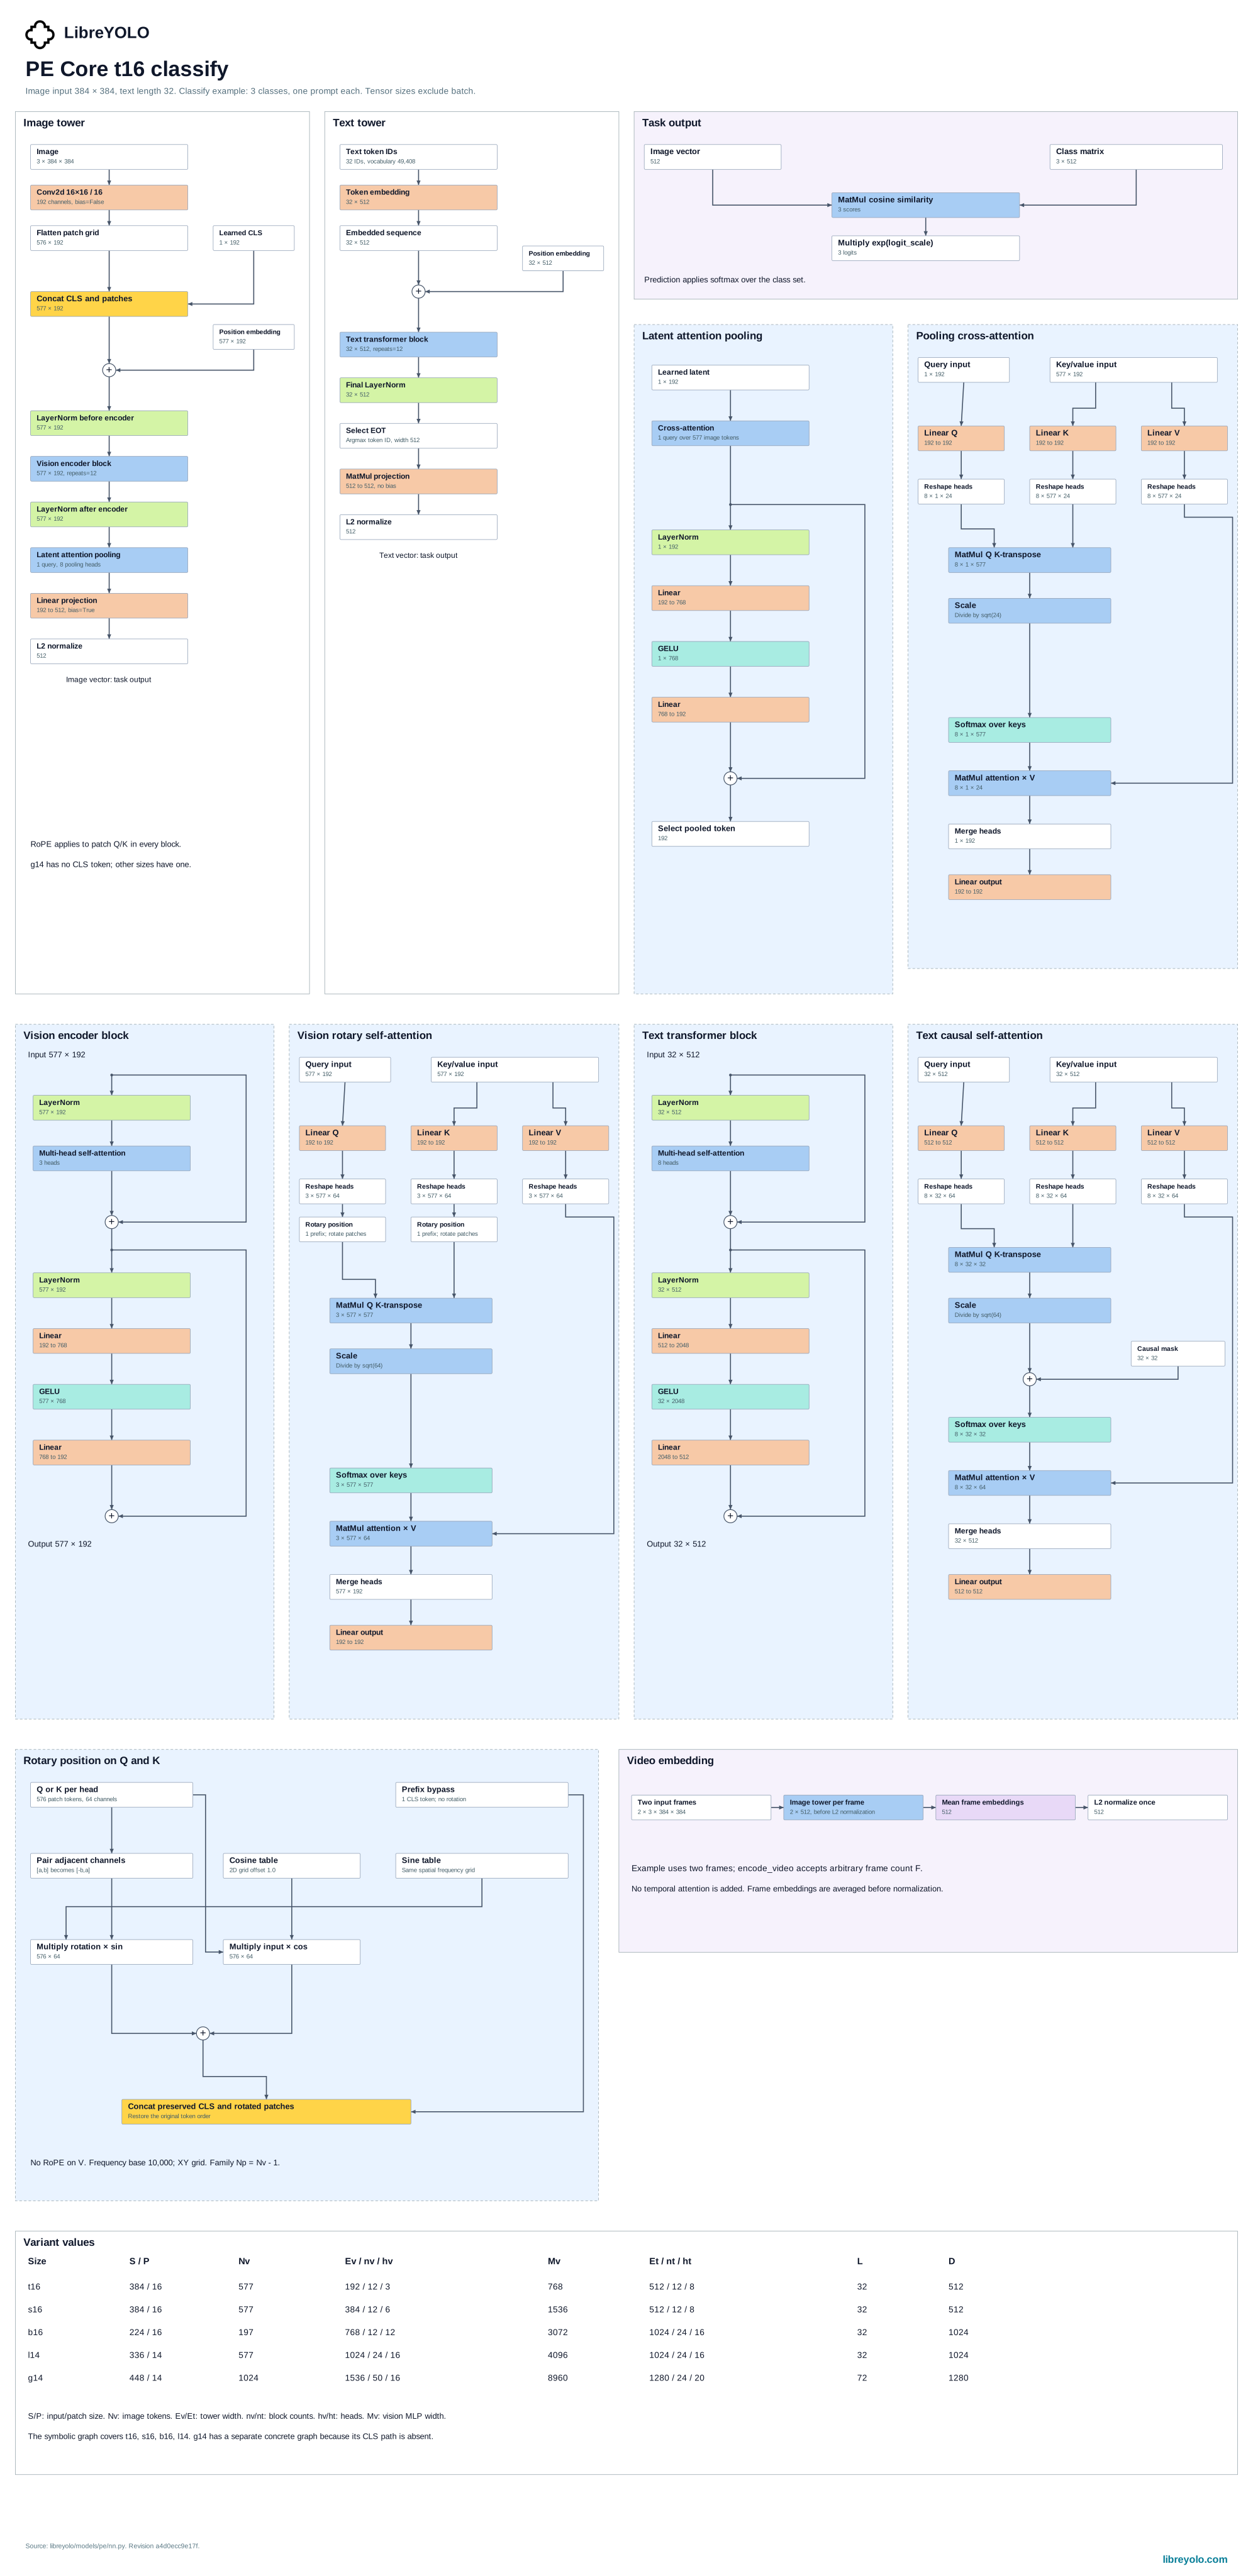
Perception Encoder maps images, text and finite video clips into a shared embedding space.
- Tác vụ
- classification, embeddings
- Cài đặt
pip install "libreyolo[clip]"- Bậc hỗ trợ
- Bậc song hành, từ v1.6.0. Một bề mặt sản phẩm riêng với factory và contract riêng.
- Giấy phép
- Mã nguồn MIT, trọng số Apache-2.0. Sử dụng thương mại
Install
pip install "libreyolo[clip]"Predict
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibrePEt16-cls.pt", device="cpu")model.set_classes(["person", "building"])result = model(SAMPLE_IMAGE)print(result.probs)Set classes before zero-shot classification. Select task="embed" when loading for embeddings. Video embedding samples clip_frames=8 frames by default, averages their vectors and L2-normalizes the result. Training is not supported. Exported video graphs take direct runtime input.
Export
| Tác vụ | ONNX | TorchScript | ExecuTorch | TensorRT | OpenVINO | Paddle | MNN | RKNN | ncnn | TFLite | CoreML | Core AI |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Classification | Classification to ONNX: được hỗ trợ | Classification to TorchScript: được hỗ trợ | Classification to ExecuTorch: được hỗ trợ | Classification to TensorRT: được hỗ trợ | Classification to OpenVINO: được hỗ trợ | Classification to Paddle: không được hỗ trợ | Classification to MNN: không được hỗ trợ | Classification to RKNN: không được hỗ trợ | Classification to ncnn: không được hỗ trợ | Classification to TFLite: không được hỗ trợ | Classification to CoreML: không được hỗ trợ | Classification to Core AI: không được hỗ trợ |
| Embeddings | Embeddings to ONNX: được hỗ trợ | Embeddings to TorchScript: được hỗ trợ | Embeddings to ExecuTorch: được hỗ trợ | Embeddings to TensorRT: được hỗ trợ | Embeddings to OpenVINO: được hỗ trợ | Embeddings to Paddle: không được hỗ trợ | Embeddings to MNN: không được hỗ trợ | Embeddings to RKNN: không được hỗ trợ | Embeddings to ncnn: không được hỗ trợ | Embeddings to TFLite: không được hỗ trợ | Embeddings to CoreML: không được hỗ trợ | Embeddings to Core AI: không được hỗ trợ |
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibrePEt16-cls.pt", device="cpu")model.export(format="onnx")Export setup lists format dependencies and loading exported artifacts.
Checkpoints
| Tệp | Giấy phép trọng số |
|---|---|
| Classification | |
| LibrePEt16-cls.pt | apache-2.0 |
| LibrePEs16-cls.pt | apache-2.0 |
| LibrePEb16-cls.pt | apache-2.0 |
| LibrePEl14-cls.pt | apache-2.0 |
| LibrePEg14-cls.pt | apache-2.0 |
Mọi tệp ở trên hiện đều có trong tổ chức LibreYOLO và được tải xuống trong lần sử dụng đầu tiên.
Licensing
Hãy kiểm tra giấy phép trong repo Hugging Face của trọng số cụ thể mà bạn tải xuống. Mỗi checkpoint trong tổ chức LibreYOLO đều có giấy phép riêng và giấy phép có thể khác nhau trong cùng một họ. Repo đó là nguồn có thẩm quyền; phần tóm tắt dưới đây mô tả các điều khoản áp dụng khi trang này được kiểm chứng lần gần nhất.
Đây là phần mô tả các giấy phép liên quan, không phải tư vấn pháp lý. Nếu câu trả lời có ý nghĩa về mặt thương mại, hãy tự đọc các giấy phép và tham khảo cố vấn của riêng bạn.
- Công trình gốc
- Perception Encoder, Meta AI
- Giấy phép thượng nguồn
- Apache-2.0
- Nguồn thượng nguồn
- github.com/facebookresearch/perception_models
- Mã nguồn LibreYOLO
- MIT
- Trọng số
- Apache-2.0, được phát hành lại tại huggingface.co/LibreYOLO
- Diễn giải
- The publisher declares Apache-2.0 for the encoder weights.
Citation
@article{bolya2025PerceptionEncoder,
  title={Perception Encoder: The best visual embeddings are not at the output of the network},
  author={Daniel Bolya and Po-Yao Huang and Peize Sun and Jang Hyun Cho and Andrea Madotto and Chen Wei and Tengyu Ma and Jiale Zhi and Jathushan Rajasegaran and Hanoona Rasheed and Junke Wang and Marco Monteiro and Hu Xu and Shiyu Dong and Nikhila Ravi and Daniel Li and Piotr Doll{\'a}r and Christoph Feichtenhofer},
  journal={arXiv:2504.13181},
  year={2025}
}
Được sao chép từ khối trích dẫn của tác giả tại raw.githubusercontent.com/facebookresearch/perception_models/main/README.md.