V-JEPA 2
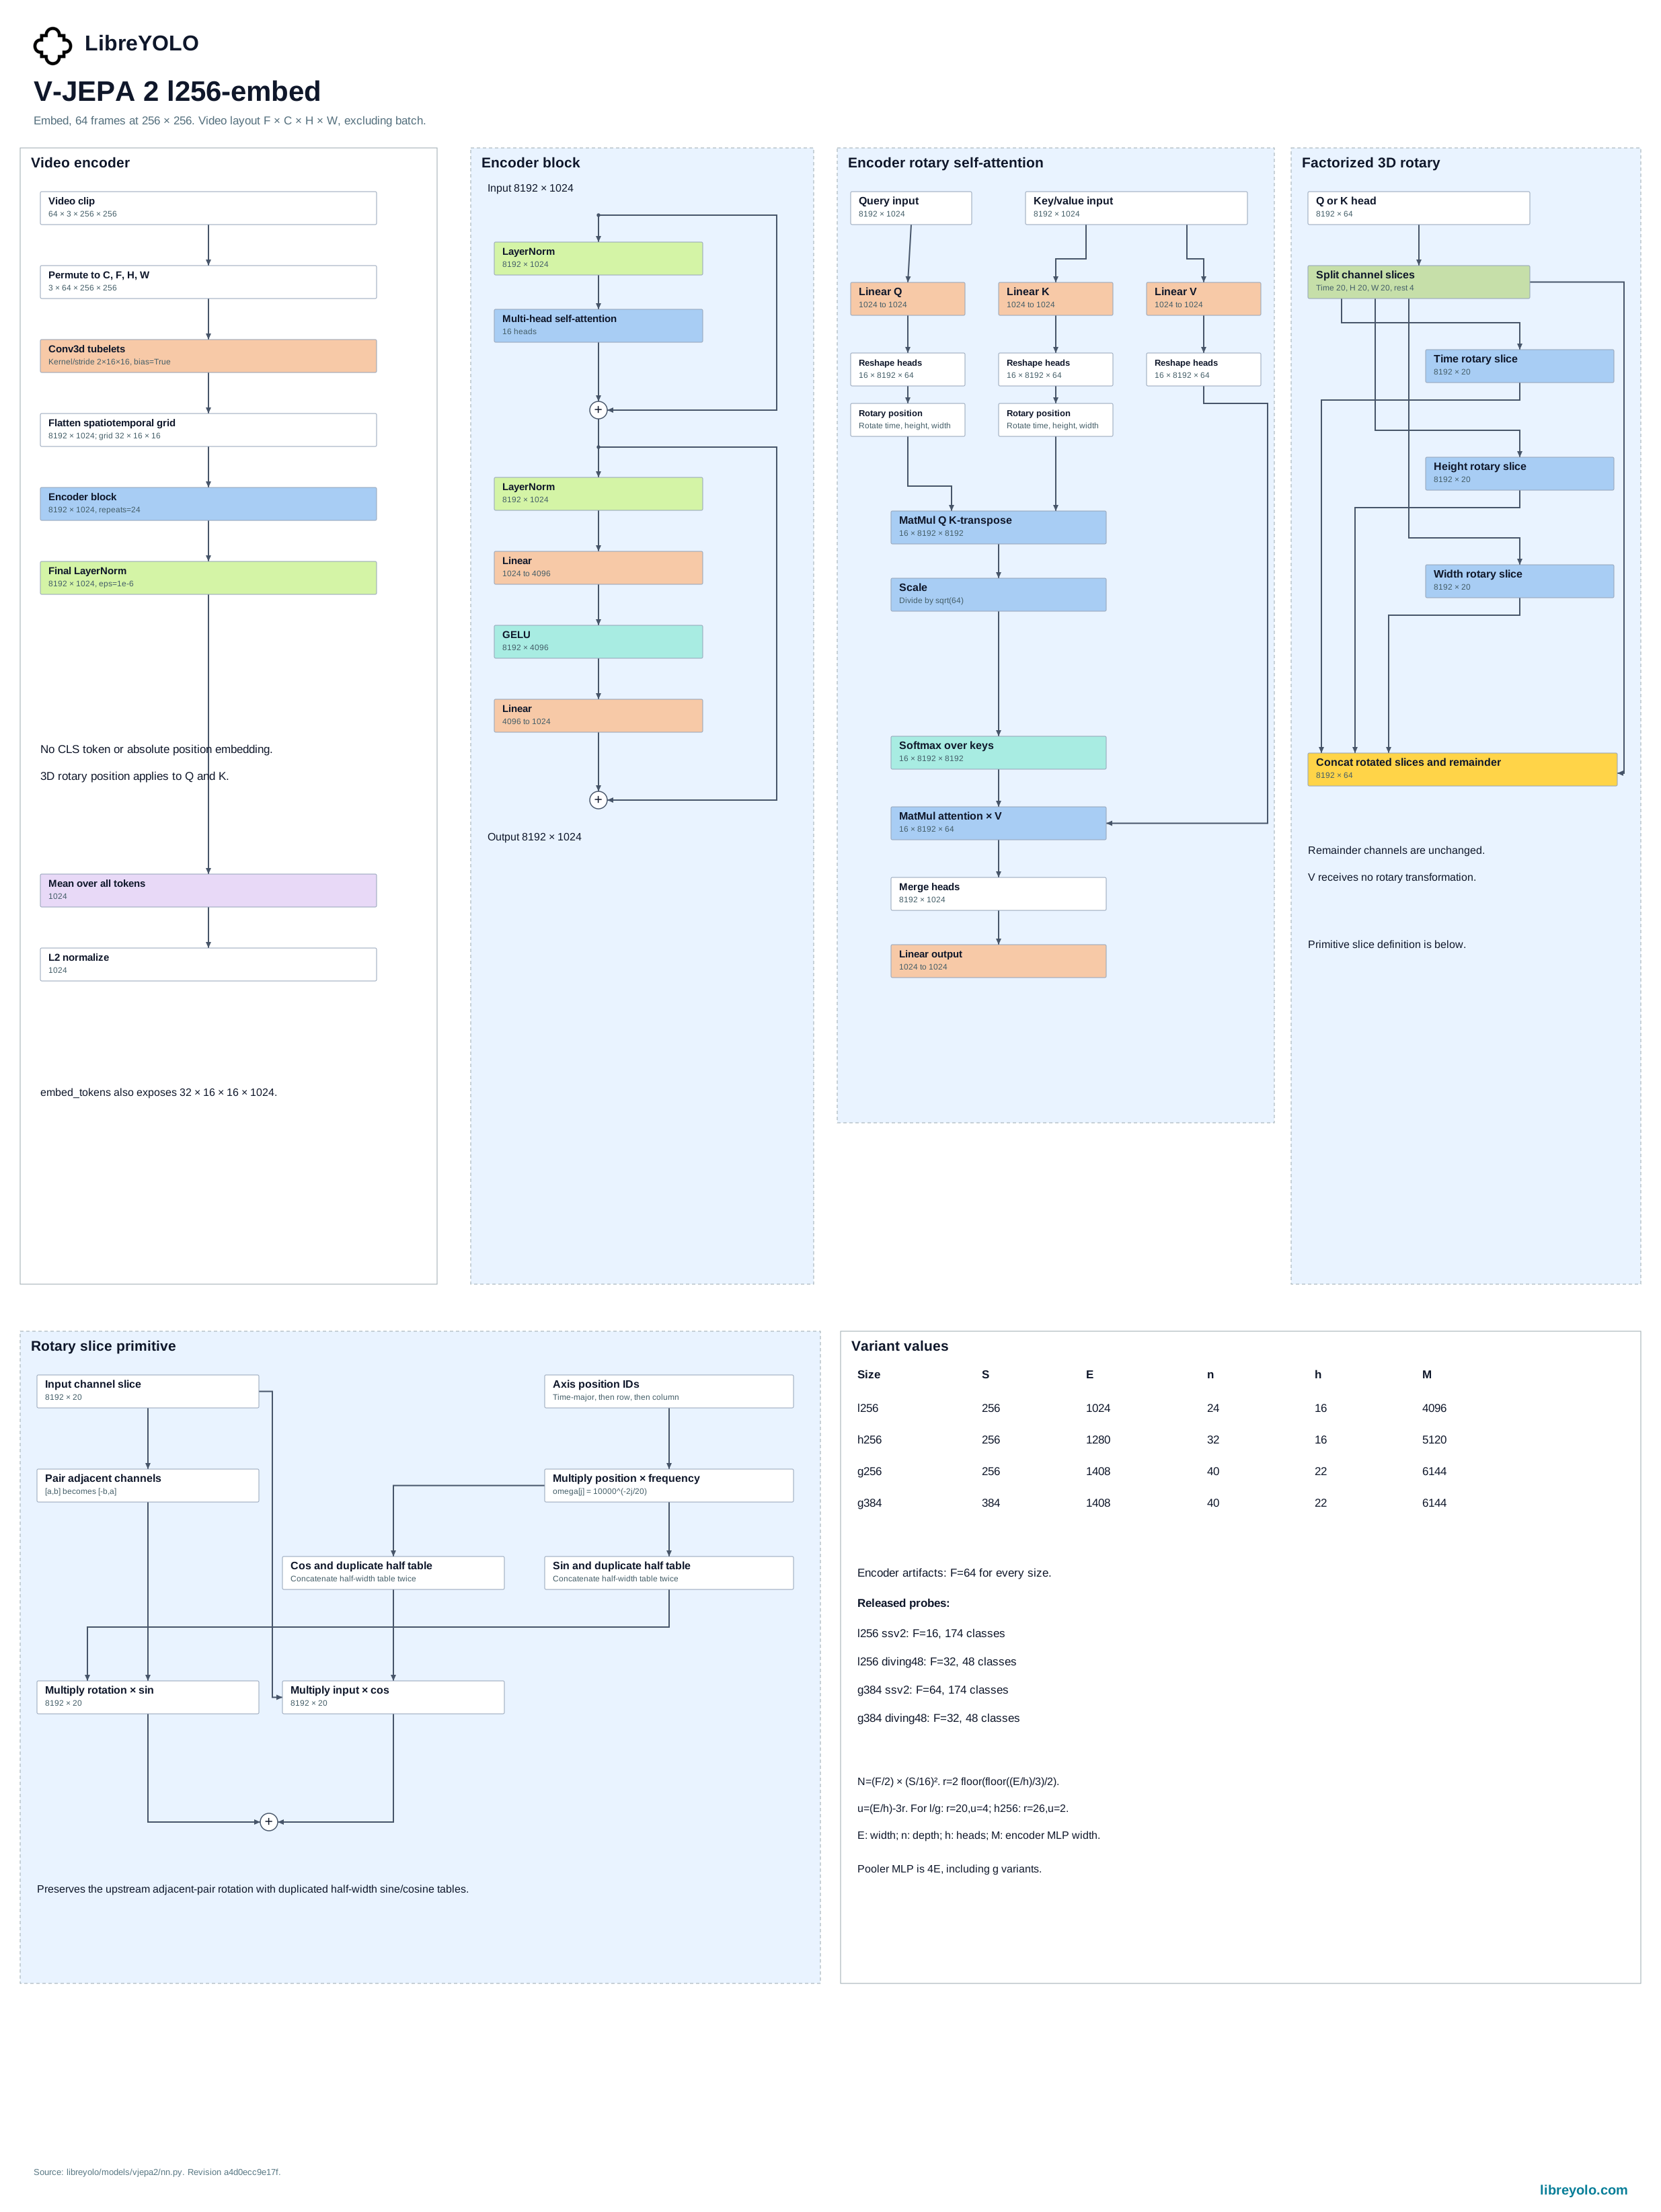
V-JEPA 2 produces video embeddings and supports training an attentive classification probe.
- Aufgaben
- embeddings, classification
- Größen
- l256, h256, g256, g384 at 256 to 384 px
- Installation
pip install libreyolo- Supportstufe
- Unterstützt, seit v1.6.0. Ergänzende trainierbare Modelle: Die CI bleibt grün, Funktionen kommen bei Gelegenheit hinzu.
- Lizenzen
- Code MIT, Gewichte MIT; Apache-2.0 for giant encoder artifacts. Kommerzielle Nutzung
Install
pip install "libreyolo"Predict
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibreVJEPA2l256-embed.pt", device="cpu")result = model(SAMPLE_IMAGE)print(result.embeddings)tokens = model.embed_tokens(SAMPLE_IMAGE)print(tokens.shape)A still image is promoted to a clip. embed_tokens() returns (B, T, H, W, D) tokens; the public embedding normalizes their mean. Exported clip graphs require direct five-dimensional runtime input.
Train
Only the attentive probe and linear classifier train; the encoder stays frozen. Use the classification task and a video-manifest dataset. Defaults are 10 epochs, batch 2, learning rate 0.001 and workers 0. Full encoder fine-tuning and pretraining are not supported.
Dataset setup describes the required training data.
from libreyolo import LibreYOLO model = LibreYOLO("LibreVJEPA2l256-cls-ssv2.pt", device="cpu")# Replace with your video dataset YAML (train/val manifests of '<video-path> <class-id>' lines).model.train(data="path/to/your/video_dataset.yaml", epochs=1, device="cpu", workers=0)Validate
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibreVJEPA2l256-cls-ssv2.pt", device="cpu")# Replace with your video dataset YAML; val() reads its val manifest of '<video-path> <class-id>' lines.metrics = model.val(data="path/to/your/video_dataset.yaml", workers=0)print(metrics)Use the dataset format for this task. Validation explains the dataset requirements and returned metrics.
Export
| Aufgabe | ONNX | TorchScript | ExecuTorch | TensorRT | OpenVINO | Paddle | MNN | RKNN | ncnn | TFLite | CoreML | Core AI |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Embeddings | Embeddings to ONNX: unterstützt | Embeddings to TorchScript: unterstützt | Embeddings to ExecuTorch: unterstützt | Embeddings to TensorRT: unterstützt | Embeddings to OpenVINO: unterstützt | Embeddings to Paddle: nicht unterstützt | Embeddings to MNN: nicht unterstützt | Embeddings to RKNN: nicht unterstützt | Embeddings to ncnn: nicht unterstützt | Embeddings to TFLite: nicht unterstützt | Embeddings to CoreML: nicht unterstützt | Embeddings to Core AI: nicht unterstützt |
| Classification | Classification to ONNX: unterstützt | Classification to TorchScript: unterstützt | Classification to ExecuTorch: unterstützt | Classification to TensorRT: unterstützt | Classification to OpenVINO: unterstützt | Classification to Paddle: nicht unterstützt | Classification to MNN: nicht unterstützt | Classification to RKNN: nicht unterstützt | Classification to ncnn: nicht unterstützt | Classification to TFLite: nicht unterstützt | Classification to CoreML: nicht unterstützt | Classification to Core AI: nicht unterstützt |
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibreVJEPA2l256-embed.pt", device="cpu")model.export(format="onnx")Export setup lists format dependencies and loading exported artifacts.
Checkpoints
| Datei | Lizenz der Gewichte |
|---|---|
| Embeddings | |
| LibreVJEPA2h256-embed.pt | mit |
| LibreVJEPA2l256-embed.pt | mit |
| LibreVJEPA2g384-embed.pt | apache-2.0 |
| LibreVJEPA2g256-embed.pt | apache-2.0 |
| Classification | |
| LibreVJEPA2l256-cls-ssv2.pt | mit |
| LibreVJEPA2l256-cls-diving48.pt | mit |
| LibreVJEPA2g384-cls-diving48.pt | mit |
| LibreVJEPA2g384-cls-ssv2.pt | mit |
Jede oben aufgeführte Datei ist heute in der LibreYOLO-Organisation verfügbar und wird bei der ersten Verwendung heruntergeladen.
Licensing
Prüfe die Lizenz im Hugging-Face-Repository der konkreten Gewichte, die du herunterlädst. Jeder Checkpoint in der LibreYOLO-Organisation hat eine Lizenz, und sie ist innerhalb einer Familie nicht immer gleich. Dieses Repository ist die maßgebliche Quelle. Die Zusammenfassung unten beschreibt den Stand bei der letzten Verifizierung dieser Seite.
Dies ist eine Beschreibung der beteiligten Lizenzen und keine Rechtsberatung. Wenn die Antwort kommerziell relevant ist, lies die Lizenzen selbst und hole eigenen Rechtsrat ein.
- Originalarbeit
- V-JEPA 2, Meta AI
- Upstream-Lizenz
- MIT; Apache-2.0 for giant encoder artifacts
- Upstream-Quelle
- github.com/facebookresearch/vjepa2
- LibreYOLO-Code
- MIT
- Gewichte
- MIT; Apache-2.0 for giant encoder artifacts, erneut unter huggingface.co/LibreYOLO veröffentlicht
- Einordnung
- Licenses differ by artifact: the two giant encoder artifacts are Apache-2.0; the other mirrored encoders and classification probes are MIT.