Perception Encoder
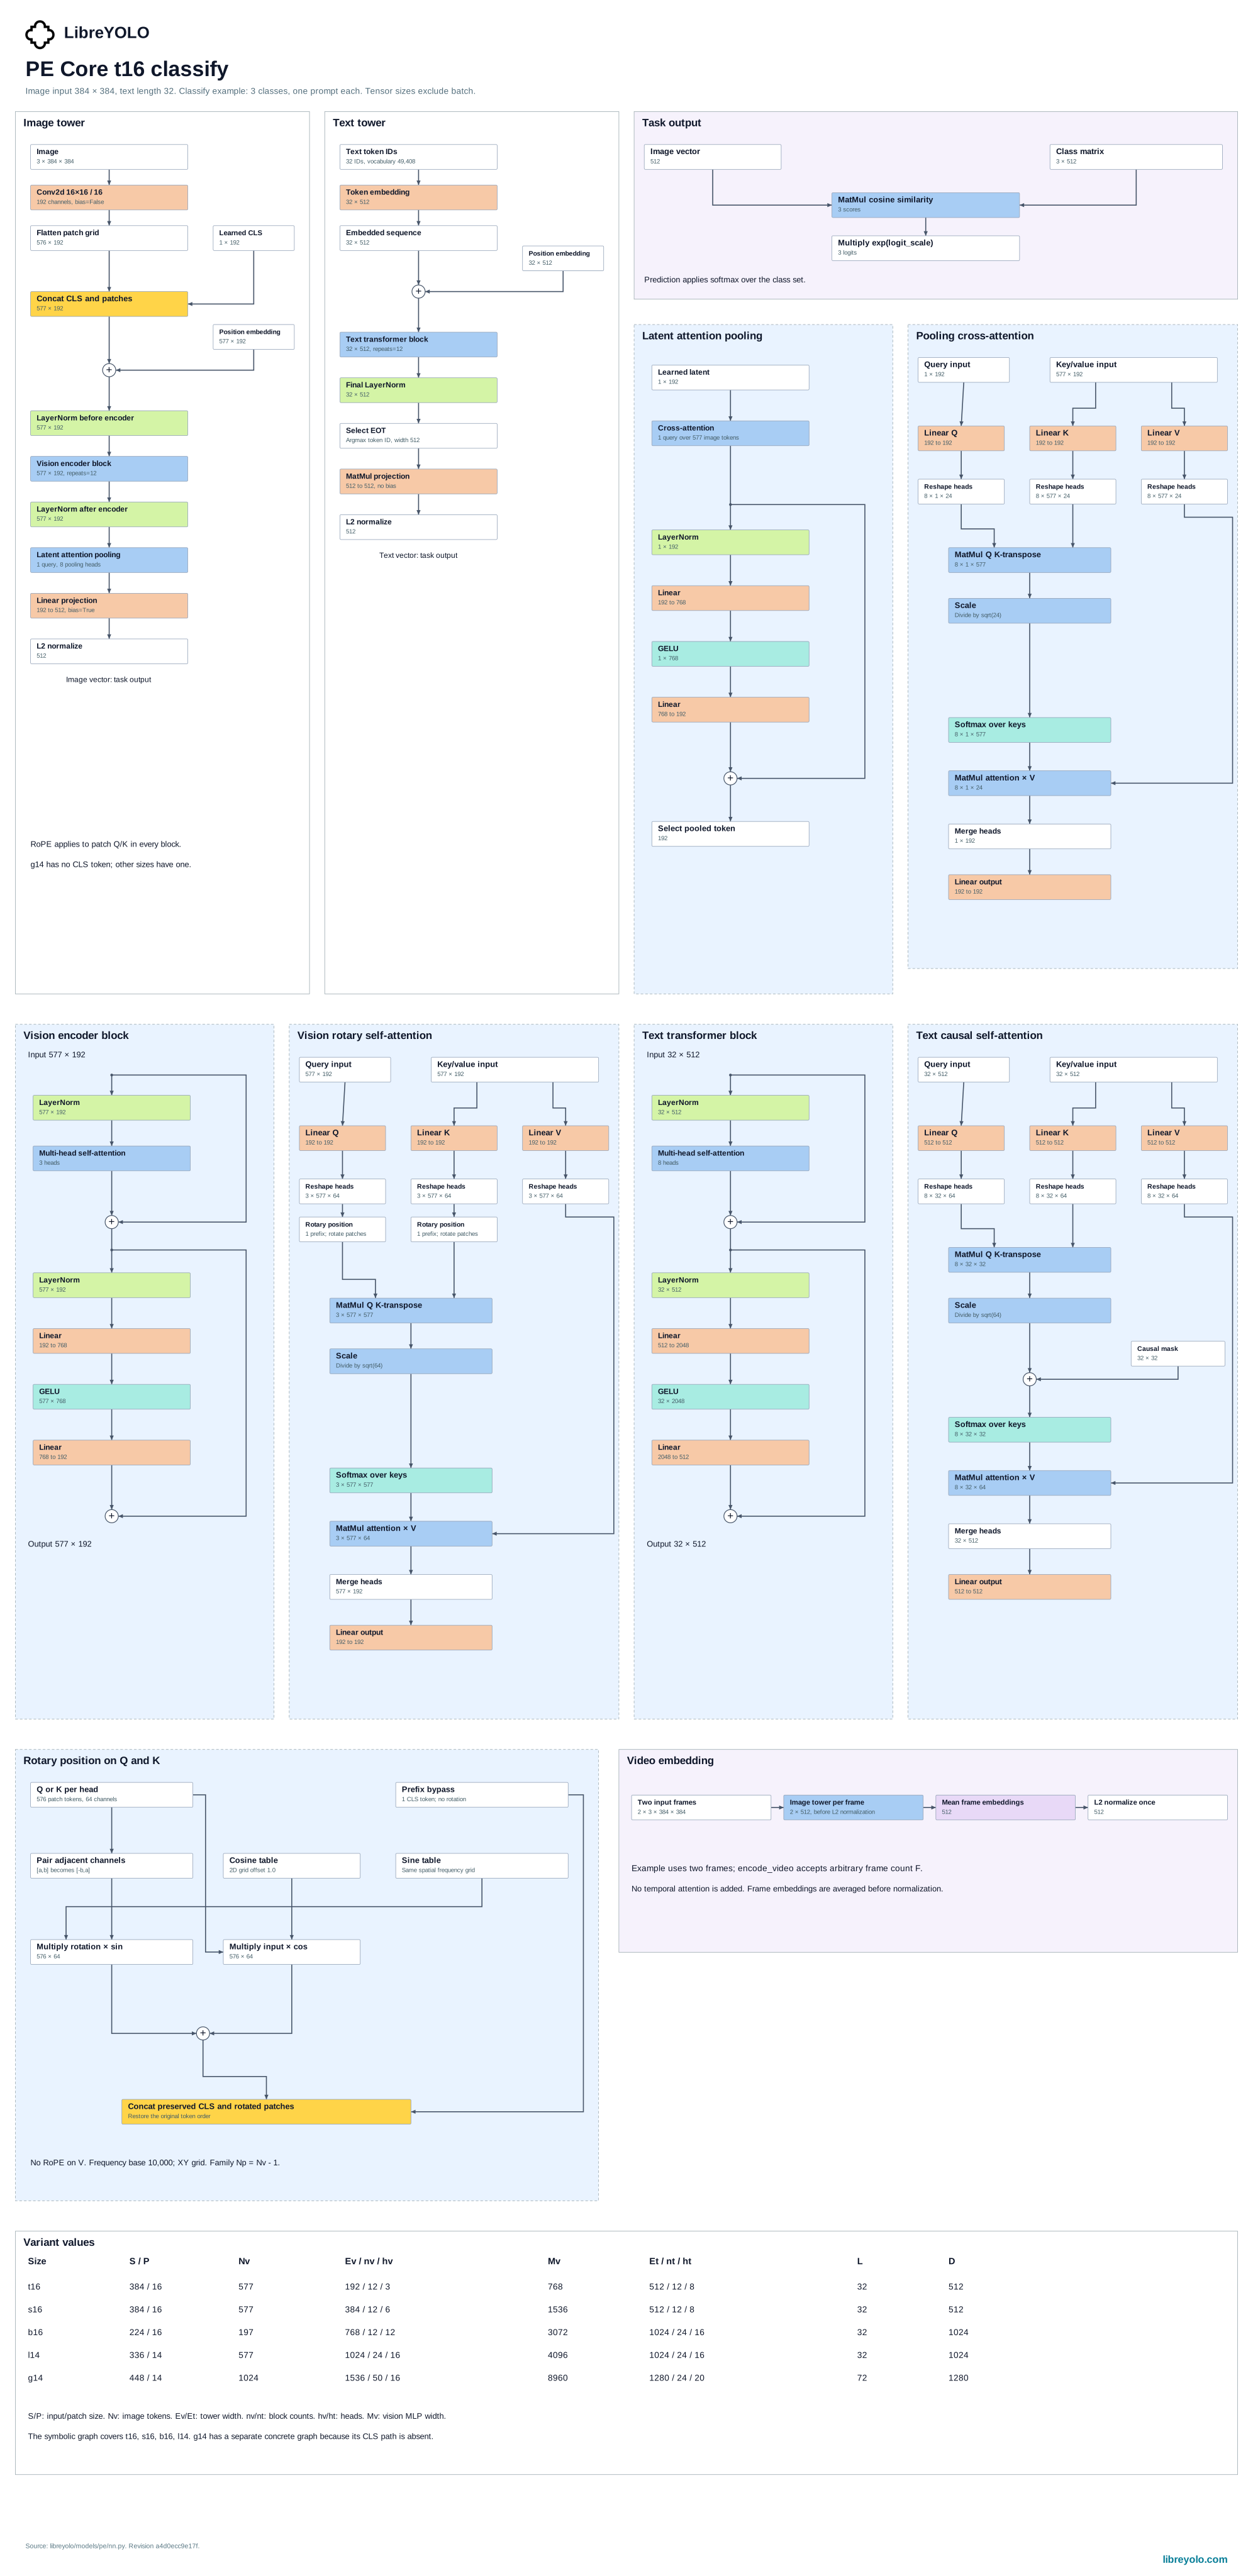
Perception Encoder maps images, text and finite video clips into a shared embedding space.
- Task
- classification, embeddings
- Installa
pip install "libreyolo[clip]"- Livello di supporto
- Livello parallelo, dalla v1.6.0. Un'interfaccia di prodotto separata, con una propria factory e un proprio contratto.
- Licenze
- Codice MIT, pesi Apache-2.0. Uso commerciale
Install
pip install "libreyolo[clip]"Predict
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibrePEt16-cls.pt", device="cpu")model.set_classes(["person", "building"])result = model(SAMPLE_IMAGE)print(result.probs)Set classes before zero-shot classification. Select task="embed" when loading for embeddings. Video embedding samples clip_frames=8 frames by default, averages their vectors and L2-normalizes the result. Training is not supported. Exported video graphs take direct runtime input.
Export
| Task | ONNX | TorchScript | ExecuTorch | TensorRT | OpenVINO | Paddle | MNN | RKNN | ncnn | TFLite | CoreML | Core AI |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Classification | Classification to ONNX: supportato | Classification to TorchScript: supportato | Classification to ExecuTorch: supportato | Classification to TensorRT: supportato | Classification to OpenVINO: supportato | Classification to Paddle: non supportato | Classification to MNN: non supportato | Classification to RKNN: non supportato | Classification to ncnn: non supportato | Classification to TFLite: non supportato | Classification to CoreML: non supportato | Classification to Core AI: non supportato |
| Embeddings | Embeddings to ONNX: supportato | Embeddings to TorchScript: supportato | Embeddings to ExecuTorch: supportato | Embeddings to TensorRT: supportato | Embeddings to OpenVINO: supportato | Embeddings to Paddle: non supportato | Embeddings to MNN: non supportato | Embeddings to RKNN: non supportato | Embeddings to ncnn: non supportato | Embeddings to TFLite: non supportato | Embeddings to CoreML: non supportato | Embeddings to Core AI: non supportato |
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibrePEt16-cls.pt", device="cpu")model.export(format="onnx")Export setup lists format dependencies and loading exported artifacts.
Checkpoints
| File | Licenza dei pesi |
|---|---|
| Classification | |
| LibrePEt16-cls.pt | apache-2.0 |
| LibrePEs16-cls.pt | apache-2.0 |
| LibrePEb16-cls.pt | apache-2.0 |
| LibrePEl14-cls.pt | apache-2.0 |
| LibrePEg14-cls.pt | apache-2.0 |
Oggi tutti i file elencati sopra sono presenti nell<link>organizzazione LibreYOLO</link> e vengono scaricati al primo utilizzo.
Licensing
Controlla la licenza nel repository Hugging Face degli specifici pesi che scarichi. Ogni checkpoint nell<link>organizzazione LibreYOLO</link> ne include una e non è sempre la stessa per tutta la famiglia. Quel repository è la fonte autorevole; il riepilogo seguente descrive le condizioni applicabili al momento dellultima verifica di questa pagina.
Questa è una descrizione delle licenze coinvolte, non una consulenza legale. Se la risposta è importante a fini commerciali, leggi personalmente le licenze e chiedi una consulenza indipendente.
- Lavoro originale
- Perception Encoder, Meta AI
- Licenza upstream
- Apache-2.0
- Sorgente upstream
- github.com/facebookresearch/perception_models
- Codice LibreYOLO
- MIT
- Pesi
- Apache-2.0, ripubblicati su huggingface.co/LibreYOLO
- Interpretazione
- The publisher declares Apache-2.0 for the encoder weights.
Citation
@article{bolya2025PerceptionEncoder,
  title={Perception Encoder: The best visual embeddings are not at the output of the network},
  author={Daniel Bolya and Po-Yao Huang and Peize Sun and Jang Hyun Cho and Andrea Madotto and Chen Wei and Tengyu Ma and Jiale Zhi and Jathushan Rajasegaran and Hanoona Rasheed and Junke Wang and Marco Monteiro and Hu Xu and Shiyu Dong and Nikhila Ravi and Daniel Li and Piotr Doll{\'a}r and Christoph Feichtenhofer},
  journal={arXiv:2504.13181},
  year={2025}
}
Copiato dal blocco di citazione degli autori disponibile su raw.githubusercontent.com/facebookresearch/perception_models/main/README.md.