V-JEPA 2
V-JEPA 2 produces video embeddings and supports training an attentive classification probe.
- Task
- embeddings, classification
- Dimensioni
- l256, h256, g256, g384 at 256 to 384 px
- Installa
pip install libreyolo- Livello di supporto
- Supportato, dalla v1.6.0. Modelli addestrabili di supporto: mantenuti funzionanti nella CI, ricevono nuove funzionalità quando possibile.
- Licenze
- Codice MIT, pesi MIT; Apache-2.0 for giant encoder artifacts. Uso commerciale
Install
pip install "libreyolo"Predict
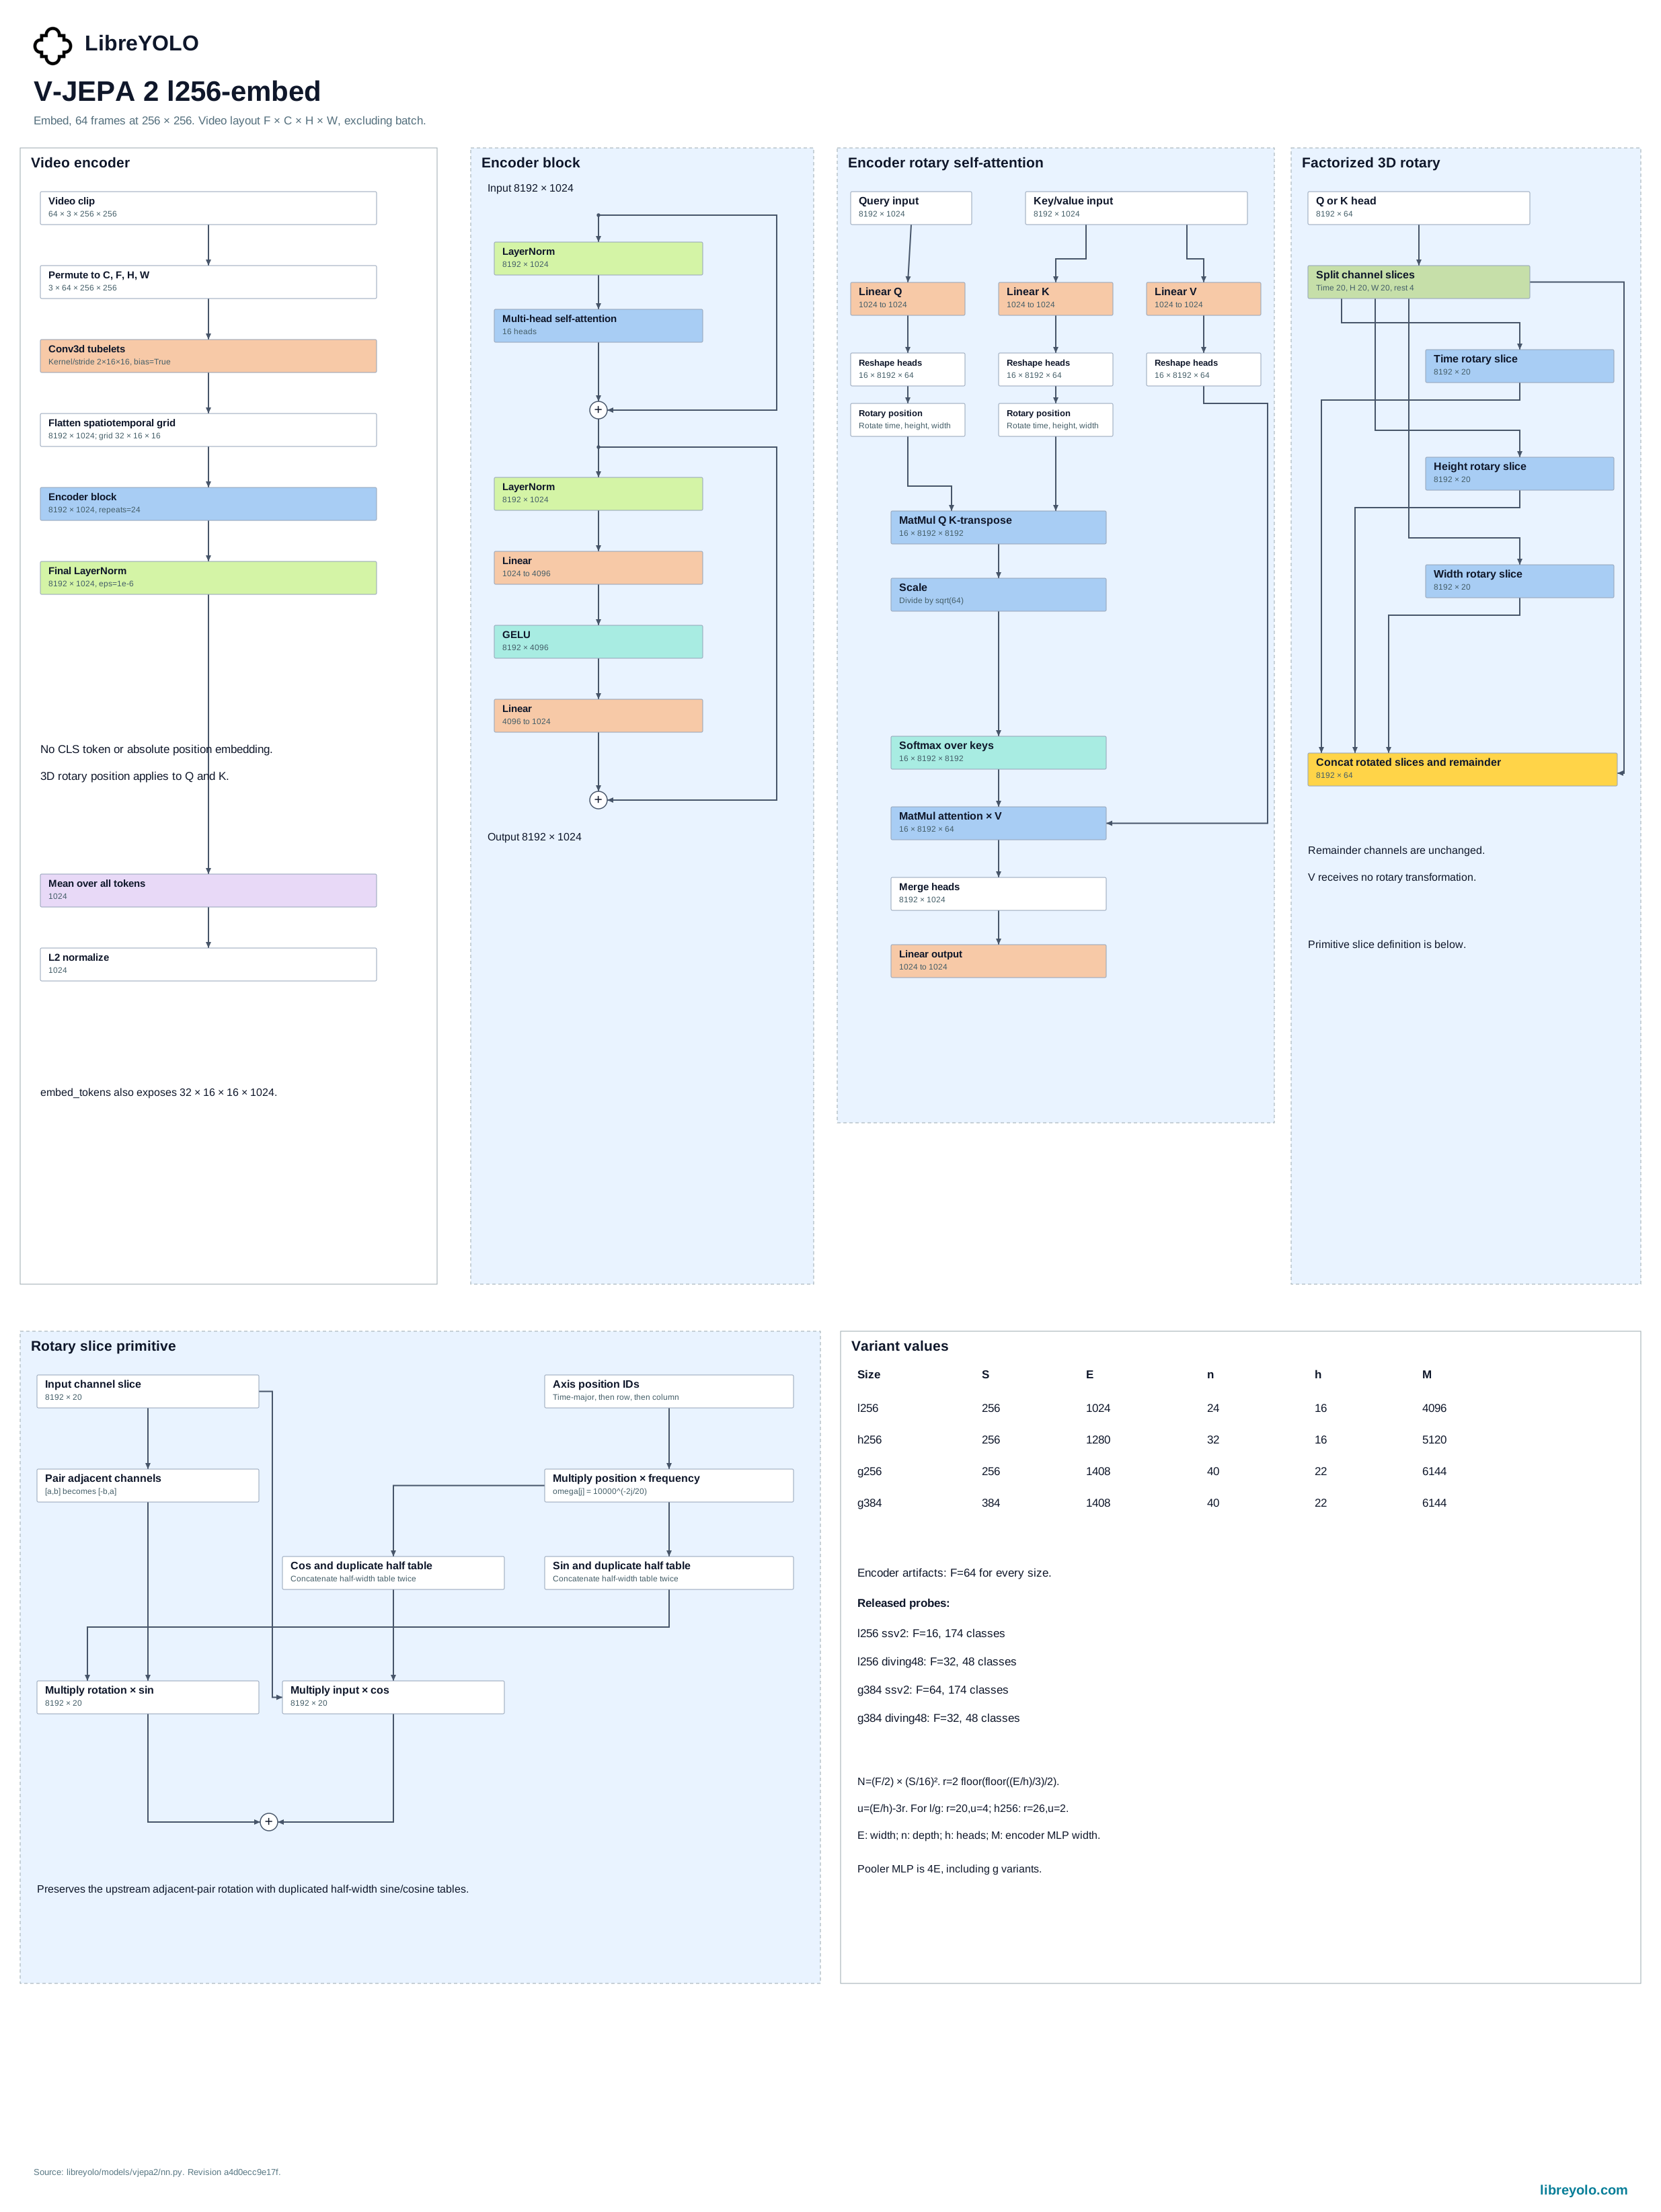
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibreVJEPA2l256-embed.pt", device="cpu")result = model(SAMPLE_IMAGE)print(result.embeddings)tokens = model.embed_tokens(SAMPLE_IMAGE)print(tokens.shape)A still image is promoted to a clip. embed_tokens() returns (B, T, H, W, D) tokens; the public embedding normalizes their mean. Exported clip graphs require direct five-dimensional runtime input.
Train
Only the attentive probe and linear classifier train; the encoder stays frozen. Use the classification task and a video-manifest dataset. Defaults are 10 epochs, batch 2, learning rate 0.001 and workers 0. Full encoder fine-tuning and pretraining are not supported.
Dataset setup describes the required training data.
from libreyolo import LibreYOLO model = LibreYOLO("LibreVJEPA2l256-cls-ssv2.pt", device="cpu")# Replace with your video dataset YAML (train/val manifests of '<video-path> <class-id>' lines).model.train(data="path/to/your/video_dataset.yaml", epochs=1, device="cpu", workers=0)Validate
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibreVJEPA2l256-cls-ssv2.pt", device="cpu")# Replace with your video dataset YAML; val() reads its val manifest of '<video-path> <class-id>' lines.metrics = model.val(data="path/to/your/video_dataset.yaml", workers=0)print(metrics)Use the dataset format for this task. Validation explains the dataset requirements and returned metrics.
Export
| Task | ONNX | TorchScript | ExecuTorch | TensorRT | OpenVINO | Paddle | MNN | RKNN | ncnn | TFLite | CoreML | Core AI |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Embeddings | Embeddings to ONNX: supportato | Embeddings to TorchScript: supportato | Embeddings to ExecuTorch: supportato | Embeddings to TensorRT: supportato | Embeddings to OpenVINO: supportato | Embeddings to Paddle: non supportato | Embeddings to MNN: non supportato | Embeddings to RKNN: non supportato | Embeddings to ncnn: non supportato | Embeddings to TFLite: non supportato | Embeddings to CoreML: non supportato | Embeddings to Core AI: non supportato |
| Classification | Classification to ONNX: supportato | Classification to TorchScript: supportato | Classification to ExecuTorch: supportato | Classification to TensorRT: supportato | Classification to OpenVINO: supportato | Classification to Paddle: non supportato | Classification to MNN: non supportato | Classification to RKNN: non supportato | Classification to ncnn: non supportato | Classification to TFLite: non supportato | Classification to CoreML: non supportato | Classification to Core AI: non supportato |
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibreVJEPA2l256-embed.pt", device="cpu")model.export(format="onnx")Export setup lists format dependencies and loading exported artifacts.
Checkpoints
| File | Licenza dei pesi |
|---|---|
| Embeddings | |
| LibreVJEPA2h256-embed.pt | mit |
| LibreVJEPA2l256-embed.pt | mit |
| LibreVJEPA2g384-embed.pt | apache-2.0 |
| LibreVJEPA2g256-embed.pt | apache-2.0 |
| Classification | |
| LibreVJEPA2l256-cls-ssv2.pt | mit |
| LibreVJEPA2l256-cls-diving48.pt | mit |
| LibreVJEPA2g384-cls-diving48.pt | mit |
| LibreVJEPA2g384-cls-ssv2.pt | mit |
Oggi tutti i file elencati sopra sono presenti nell<link>organizzazione LibreYOLO</link> e vengono scaricati al primo utilizzo.
Licensing
Controlla la licenza nel repository Hugging Face degli specifici pesi che scarichi. Ogni checkpoint nell<link>organizzazione LibreYOLO</link> ne include una e non è sempre la stessa per tutta la famiglia. Quel repository è la fonte autorevole; il riepilogo seguente descrive le condizioni applicabili al momento dellultima verifica di questa pagina.
Questa è una descrizione delle licenze coinvolte, non una consulenza legale. Se la risposta è importante a fini commerciali, leggi personalmente le licenze e chiedi una consulenza indipendente.
- Lavoro originale
- V-JEPA 2, Meta AI
- Licenza upstream
- MIT; Apache-2.0 for giant encoder artifacts
- Sorgente upstream
- github.com/facebookresearch/vjepa2
- Codice LibreYOLO
- MIT
- Pesi
- MIT; Apache-2.0 for giant encoder artifacts, ripubblicati su huggingface.co/LibreYOLO
- Interpretazione
- Licenses differ by artifact: the two giant encoder artifacts are Apache-2.0; the other mirrored encoders and classification probes are MIT.