V-JEPA 2
V-JEPA 2 produces video embeddings and supports training an attentive classification probe.
- 任务
- embeddings, classification
- 尺寸
- l256, h256, g256, g384 at 256 to 384 px
- 安装
pip install libreyolo- 支持层级
- 已支持,自 v1.6.0 起。起支撑作用的可训练家族:在 CI 里保持绿色,功能视情况落地。
- 许可
- 代码采用 MIT,权重采用 MIT; Apache-2.0 for giant encoder artifacts。商用
Install
pip install "libreyolo"Predict
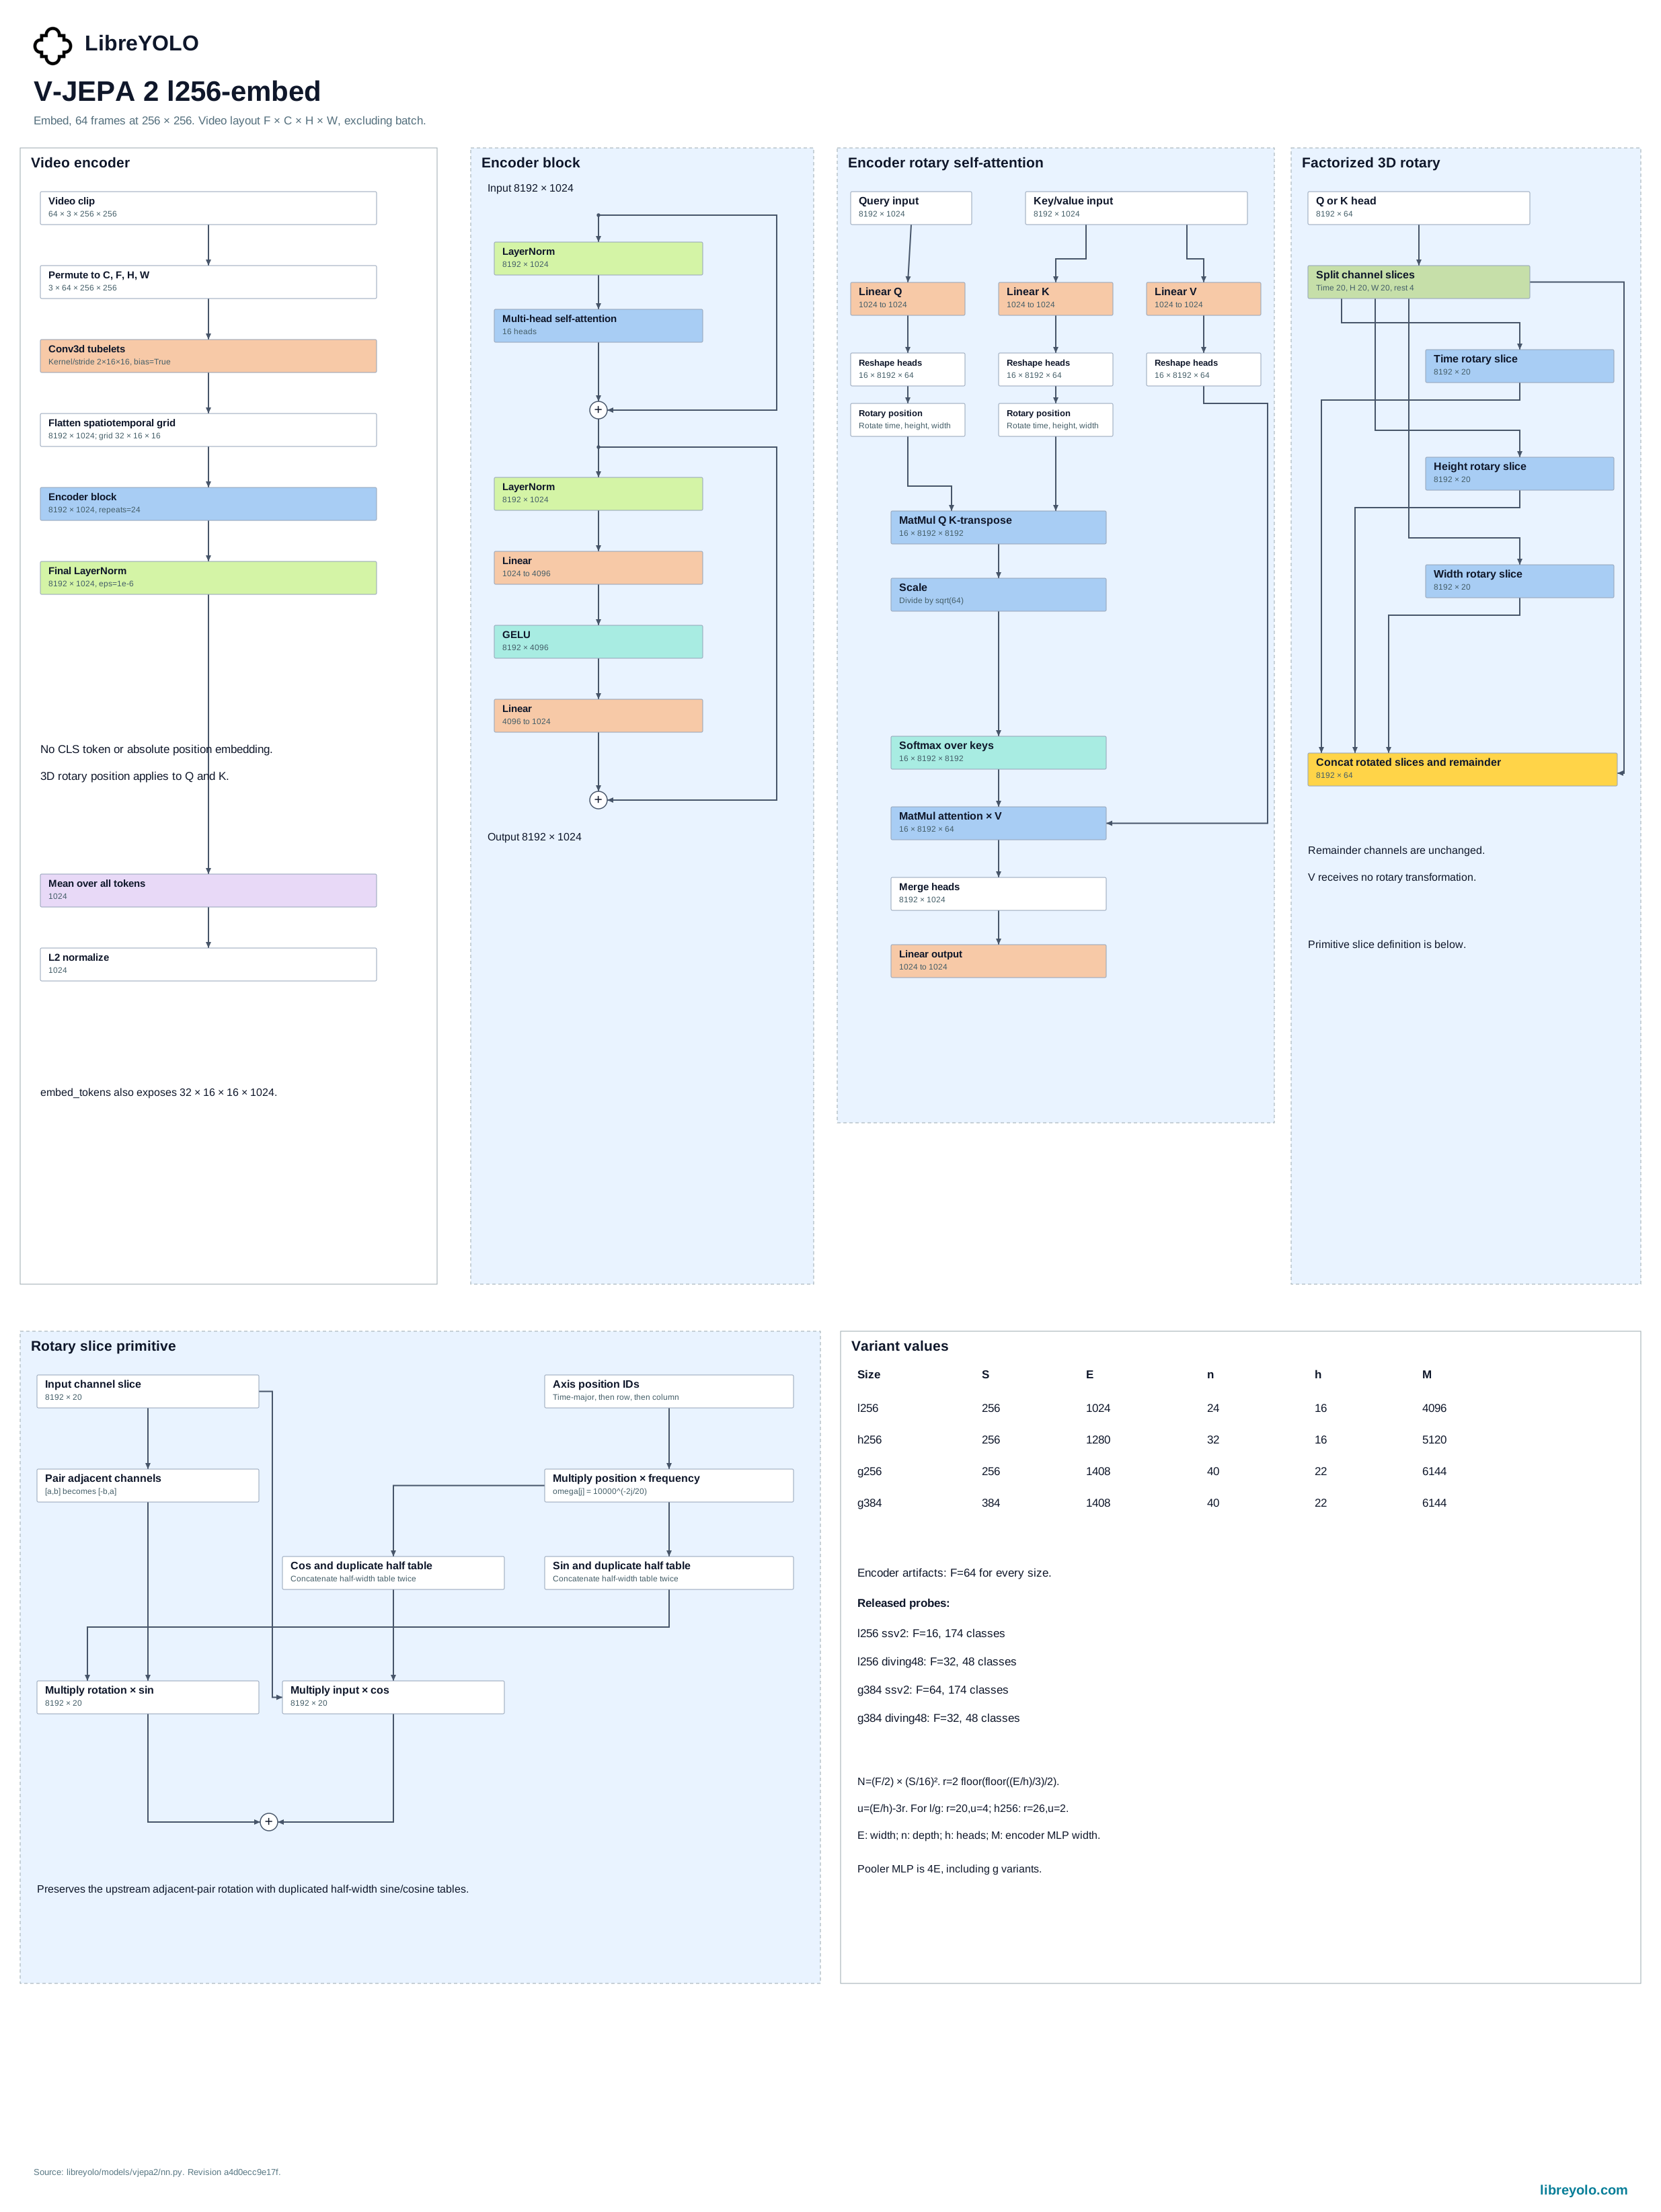
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibreVJEPA2l256-embed.pt", device="cpu")result = model(SAMPLE_IMAGE)print(result.embeddings)tokens = model.embed_tokens(SAMPLE_IMAGE)print(tokens.shape)A still image is promoted to a clip. embed_tokens() returns (B, T, H, W, D) tokens; the public embedding normalizes their mean. Exported clip graphs require direct five-dimensional runtime input.
Train
Only the attentive probe and linear classifier train; the encoder stays frozen. Use the classification task and a video-manifest dataset. Defaults are 10 epochs, batch 2, learning rate 0.001 and workers 0. Full encoder fine-tuning and pretraining are not supported.
Dataset setup describes the required training data.
from libreyolo import LibreYOLO model = LibreYOLO("LibreVJEPA2l256-cls-ssv2.pt", device="cpu")# Replace with your video dataset YAML (train/val manifests of '<video-path> <class-id>' lines).model.train(data="path/to/your/video_dataset.yaml", epochs=1, device="cpu", workers=0)Validate
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibreVJEPA2l256-cls-ssv2.pt", device="cpu")# Replace with your video dataset YAML; val() reads its val manifest of '<video-path> <class-id>' lines.metrics = model.val(data="path/to/your/video_dataset.yaml", workers=0)print(metrics)Use the dataset format for this task. Validation explains the dataset requirements and returned metrics.
Export
| 任务 | ONNX | TorchScript | ExecuTorch | TensorRT | OpenVINO | Paddle | MNN | RKNN | ncnn | TFLite | CoreML | Core AI |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Embeddings | Embeddings to ONNX:支持 | Embeddings to TorchScript:支持 | Embeddings to ExecuTorch:支持 | Embeddings to TensorRT:支持 | Embeddings to OpenVINO:支持 | Embeddings to Paddle:不支持 | Embeddings to MNN:不支持 | Embeddings to RKNN:不支持 | Embeddings to ncnn:不支持 | Embeddings to TFLite:不支持 | Embeddings to CoreML:不支持 | Embeddings to Core AI:不支持 |
| Classification | Classification to ONNX:支持 | Classification to TorchScript:支持 | Classification to ExecuTorch:支持 | Classification to TensorRT:支持 | Classification to OpenVINO:支持 | Classification to Paddle:不支持 | Classification to MNN:不支持 | Classification to RKNN:不支持 | Classification to ncnn:不支持 | Classification to TFLite:不支持 | Classification to CoreML:不支持 | Classification to Core AI:不支持 |
from libreyolo import LibreYOLO, SAMPLE_IMAGE model = LibreYOLO("LibreVJEPA2l256-embed.pt", device="cpu")model.export(format="onnx")Export setup lists format dependencies and loading exported artifacts.
Checkpoints
| 文件 | 权重许可 |
|---|---|
| Embeddings | |
| LibreVJEPA2h256-embed.pt | mit |
| LibreVJEPA2l256-embed.pt | mit |
| LibreVJEPA2g384-embed.pt | apache-2.0 |
| LibreVJEPA2g256-embed.pt | apache-2.0 |
| Classification | |
| LibreVJEPA2l256-cls-ssv2.pt | mit |
| LibreVJEPA2l256-cls-diving48.pt | mit |
| LibreVJEPA2g384-cls-diving48.pt | mit |
| LibreVJEPA2g384-cls-ssv2.pt | mit |
上面的每个文件目前都在 LibreYOLO 组织中,并会在首次使用时下载。
Licensing
请检查你所下载的具体权重在 Hugging Face 仓库中的许可。LibreYOLO 组织里的每个检查点都附有许可,同一家族内也不一定相同。该仓库是权威来源;以下摘要说明本页上次验证时适用的情况。
这里只说明涉及的许可证,不构成法律意见。如果答案对商用很重要,请自行阅读许可证并咨询法律顾问。
- 原始工作
- V-JEPA 2, Meta AI
- 上游许可
- MIT; Apache-2.0 for giant encoder artifacts
- LibreYOLO 代码
- MIT
- 权重
- 采用 MIT; Apache-2.0 for giant encoder artifacts 许可,重新发布在 huggingface.co/LibreYOLO
- 解读
- Licenses differ by artifact: the two giant encoder artifacts are Apache-2.0; the other mirrored encoders and classification probes are MIT.